LiveResearch Team
Your items, pasted or typed
List three or more items under Items, or paste them one per line with Bulk edit. There’s no upper limit, though 8 to 30 is typical.
MaxDiff question · Ranking
Find out what matters most on a long list. People pick the most and least important item in a few small sets. Hierarchical Bayes then gives every item a share of preference, a likely range and a tier, with count scores for a quick look.
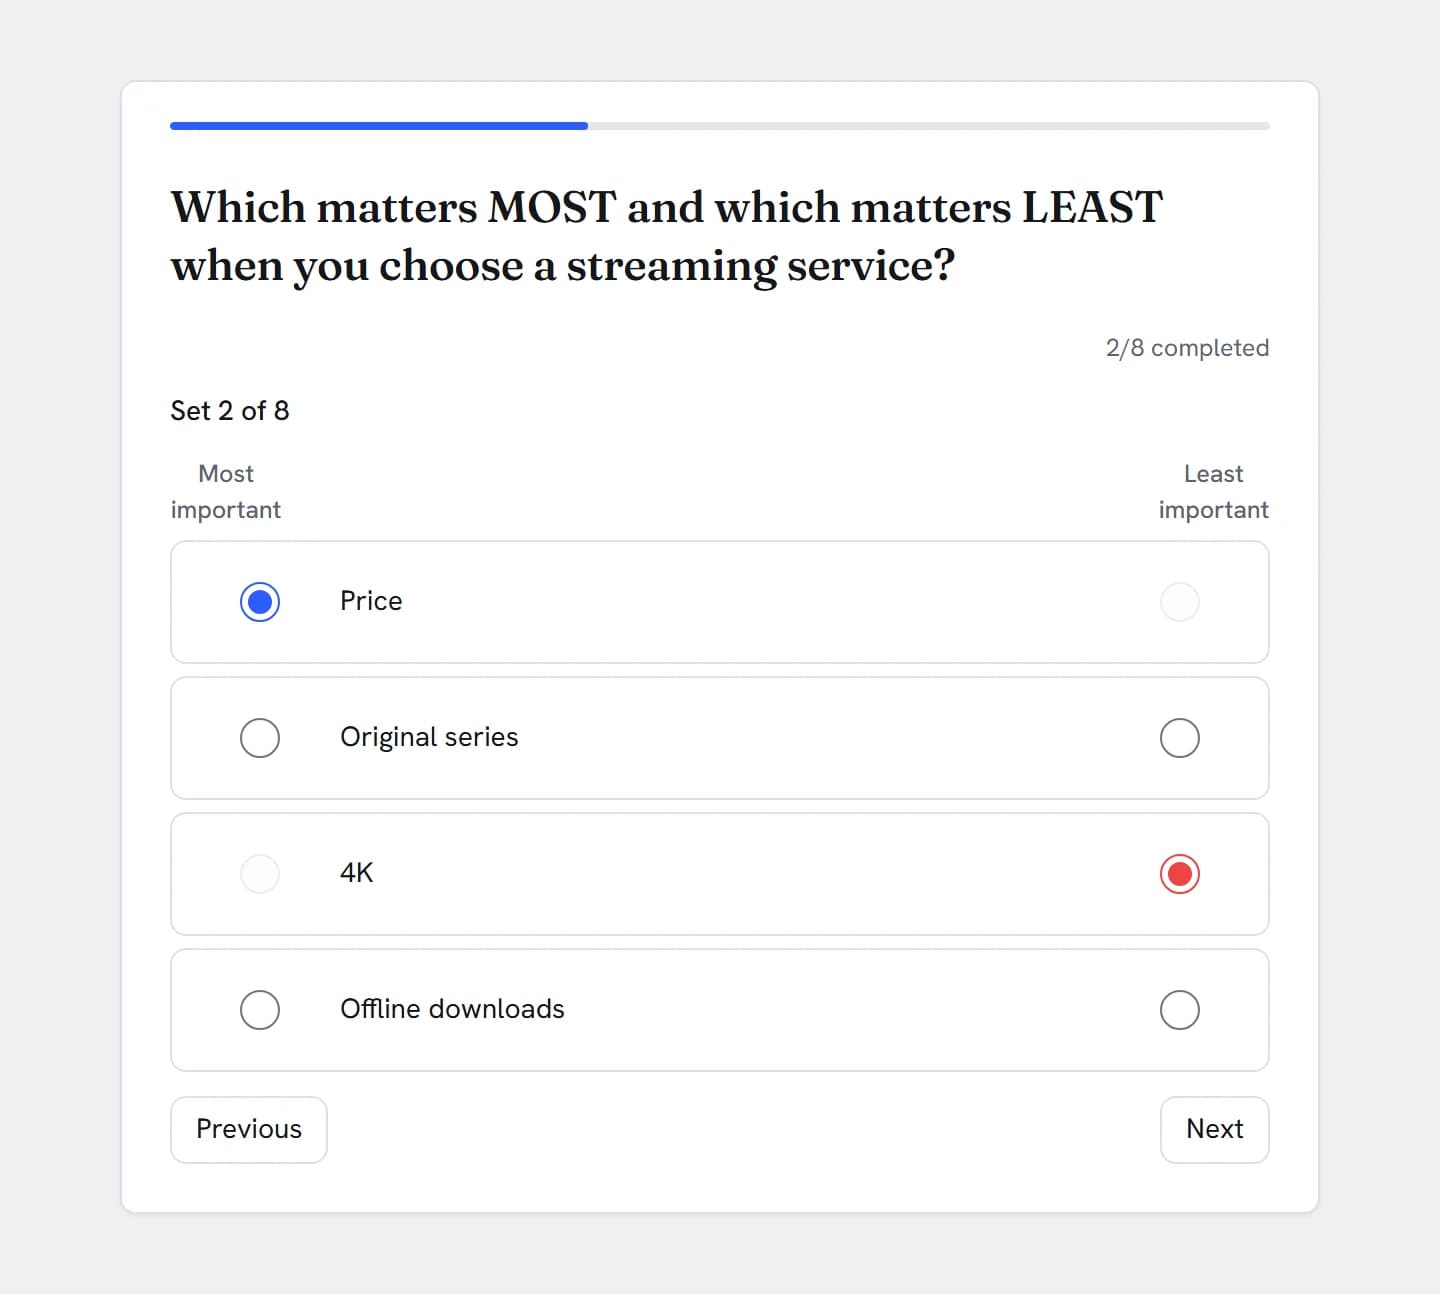
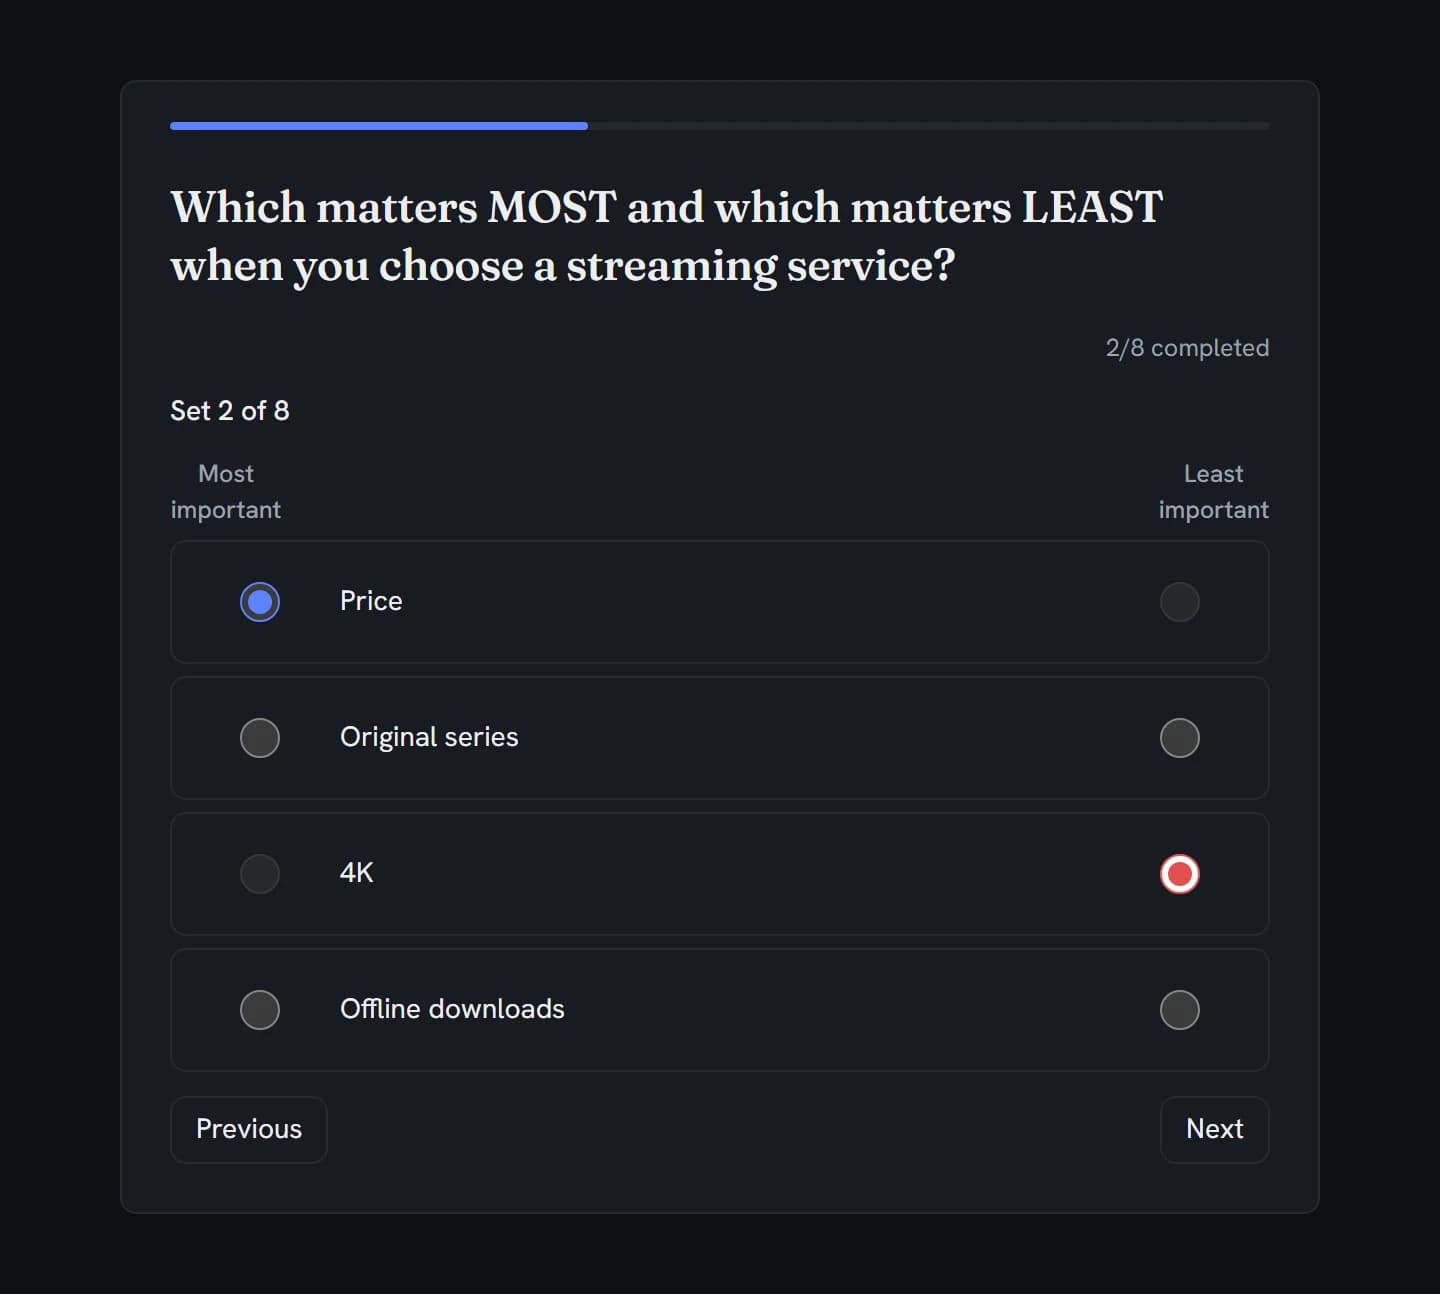
Live demo
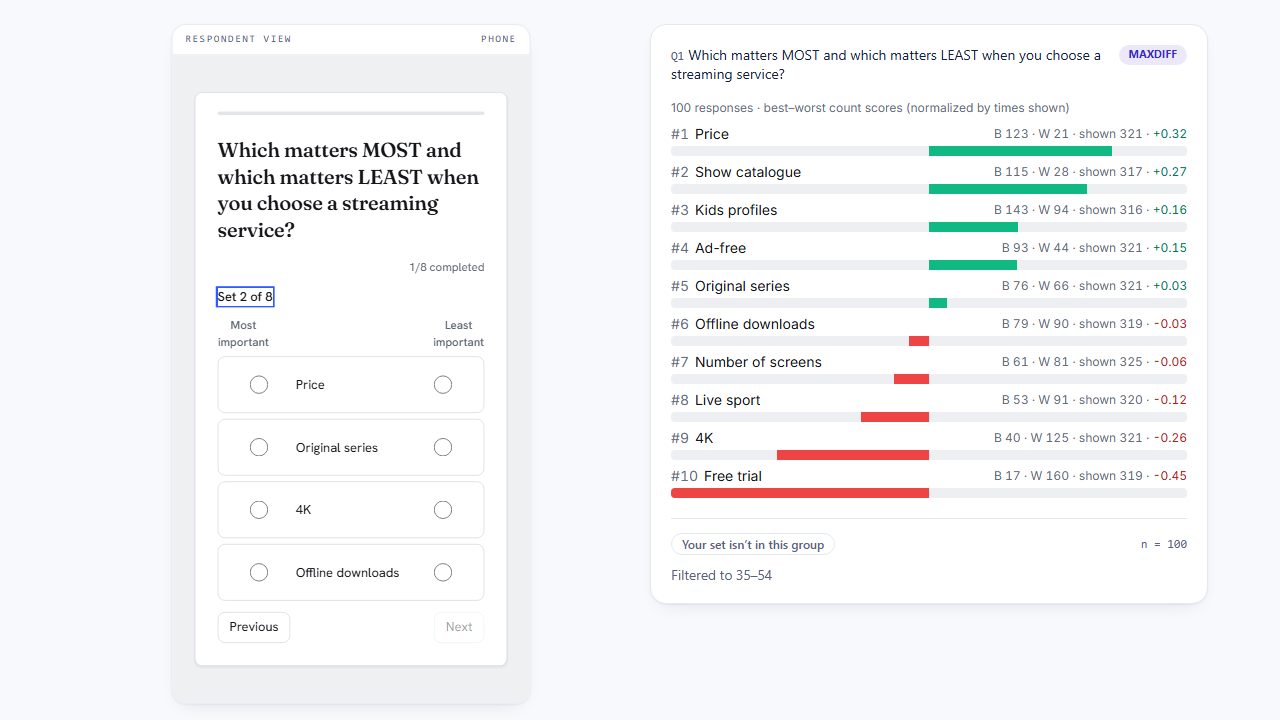
This is the question your respondents get, one small set at a time. Pick one item at each end, and the count scores beside it recalculate with your set counted. HB scores are a run you start on the Results tab.
Which matters MOST and which matters LEAST when you choose a streaming service?
In action
Every feature
Balanced sets drawn for each respondent, a respondent view that works by keyboard and screen reader, and Hierarchical Bayes scores in tiers with a quality check, plus count scores you can weight (Research Team) and filter.
List three or more items under Items, or paste them one per line with Bulk edit. There’s no upper limit, though 8 to 30 is typical.
Choose items per set (2 to 6) and the number of sets (up to 30). The hint shows how often each item will appear, and a recommended design is one click away when the list changes.
Questions you import from Excel, draft with AI or start from a template run as sets too, with the recommended design until you change it.
Tick Anchored (dual response) and each set ends by asking how many of its items actually matter: All of them, Some of them or None of them. Reword the prompt and the three answers if you like.
Set the labels at each end, such as Most important and Least important, or Most and Least appealing. The default is Best and Worst.
Required by default: every set needs a pick at each end, and the anchor when it’s on.
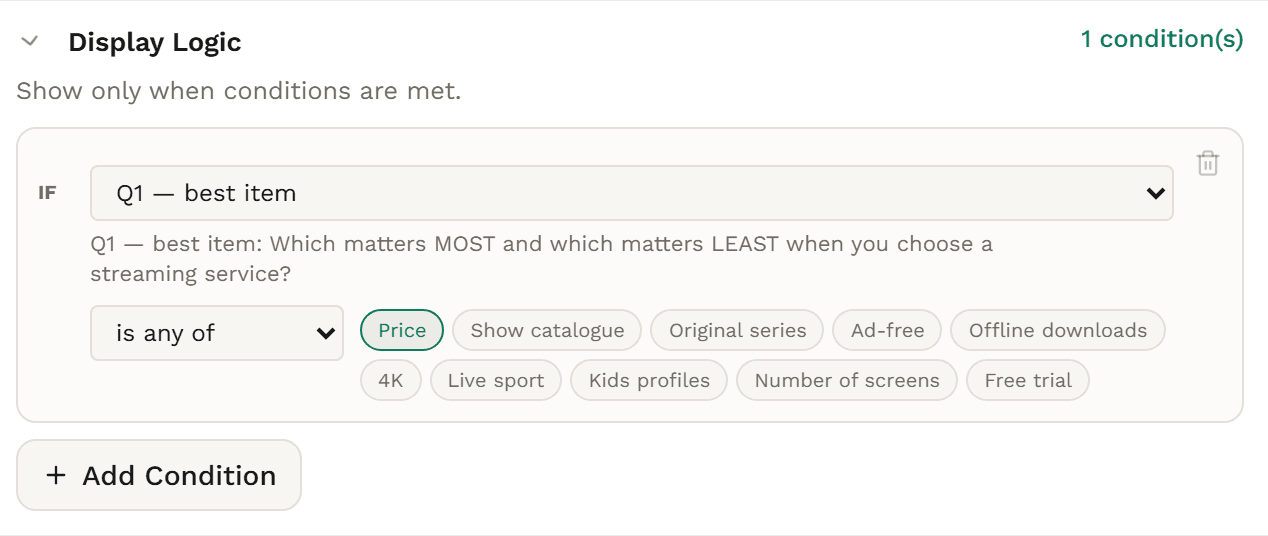
Show or skip questions on the best or worst item, or pipe it into a later question’s wording.
The best item is the one a person picked as most important most often.
Give an item display logic and people who shouldn’t see it never do: it stays out of their sets.
A MAXDIFF row in an Excel sheet, or a MaxDiff in an AI-drafted survey, comes in ready to run as sets.
Qualtrics MaxDiff projects don’t import.
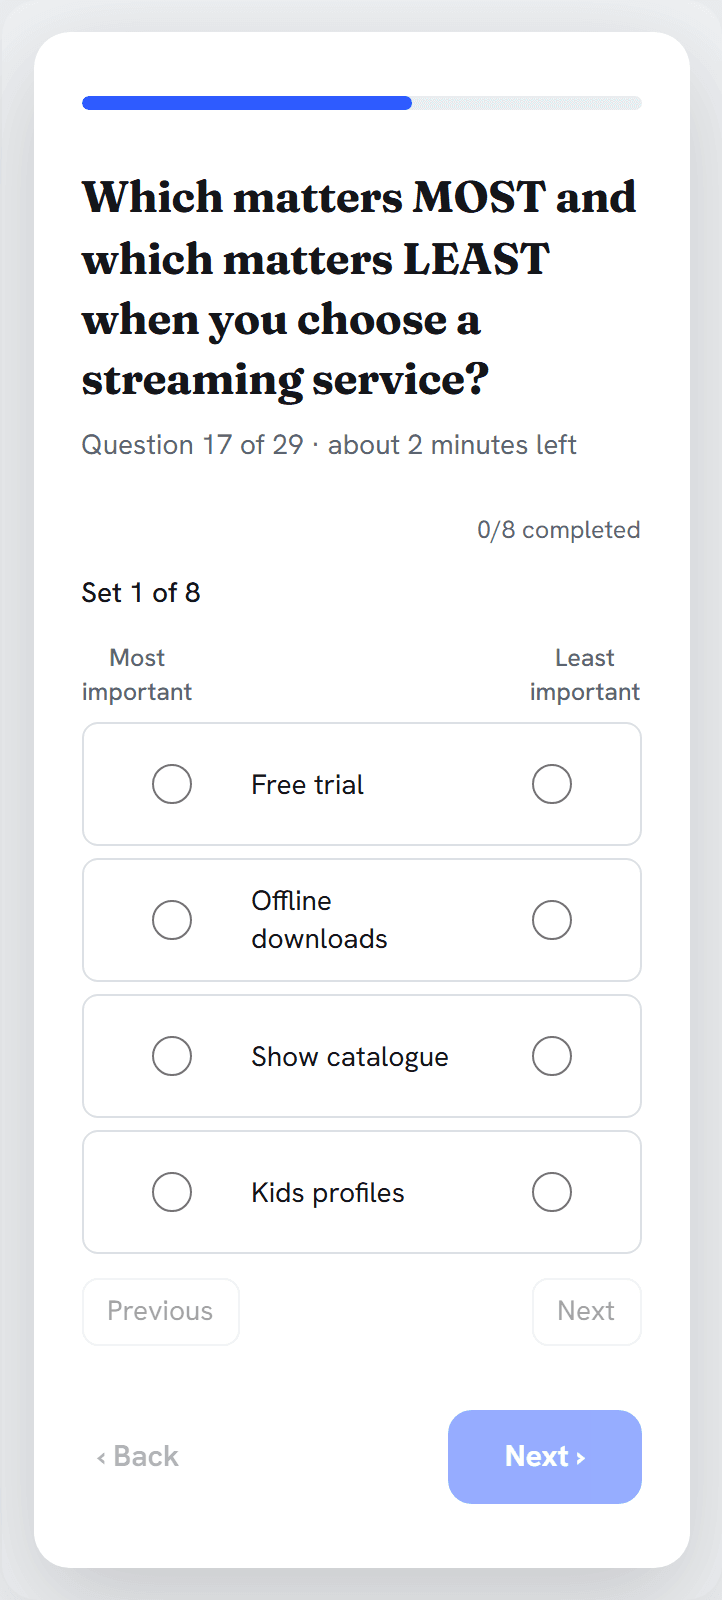
“Set 2 of 8” at the top and a count of finished sets, with Previous and Next to move between them.
Each person gets their own sets: every item shown about as often as the others, pairs spread out, the order shuffled in each set, and no set repeated when the list allows it.
Pick an item at one end and its pick at the other end turns off, so nobody can choose the same item as most and least important.
The server rebuilds each person’s sets from their seed, and the sets are saved with the answer. A submission must match them: this question’s items, every set, the right size.
Someone who comes back later sees the same sets they started with.
Items, end labels and any anchor wording you write go into the translation sheet. “Set 2 of 8”, Previous and Next come translated in six languages.
Each set is a named group, each pick names its end and item, and focus moves to the new set.
The same layout on any screen, with a 44px tap area on every pick by default. Long items wrap in the middle.
Cards, buttons and picks follow the survey’s theme and dark mode, and mirror for right-to-left languages.
Hierarchical Bayes gives each item a share of preference, out of 100 across the list, with a 95% likely range and its chance of a top-3 place. Items the data can’t tell apart share a tier.
Score with HB once the Results base has 50 respondents. Each run follows the Results filter and weighting (Research Team), and the card tells you when new responses have come in since.
A badge reads Rankings stable when the model has settled and two independent runs inside it agree on every clear tier boundary. Otherwise it reads Still settling, and more responses will help.
Each run compares every respondent’s fit (RLH) with a cut-off simulated from 200 random respondents answering your design. See who is flagged, preview the scores without them, or remove them and re-fit. Restore brings them back.
Flagged people stay in until you remove them. Some valid respondents also fall below the cut-off, and the card says so.
For a quick view, Results also ranks every item by its count score, from −1 to +1, on a bar around zero.
Under each item, as B, W and shown: how many times it was picked at each end, and how often it was shown.
Weight the survey and every pick and showing counts the person’s weight, on the count card and in the count-scores file. HB averages each person’s shares with the same weights.
Filter Results by another question, such as age, and the count scores re-rank for that group. Re-run HB to score that group too.
One group at a time; differences aren’t tested.
With an anchor, each item also shows its % above threshold: the share of anchored answers that put it above the “actually matters” line.
Clients with portal access see the ranked count-score card.
Q1_set1_best and Q1_set1_worst through the last set, holding item codes, plus the anchor when it’s on.
Export scores on the HB card gives each respondent’s share and raw HB utility for every item, with their RLH, the flag and whether they were removed. CSV, Excel or SPSS.
Excel adds a summary sheet and a Notes sheet; SPSS labels each variable with its item.
Every item each person saw, set by set, with both picks marked: the long format, for your own model if you want one, in R, or Sawtooth after reshaping.
The download on the Results tab gives the count scores, ranked by item, as CSV or Excel, with the same people, filters and weights (Research Team) as the count card.
Each Excel export adds a MaxDiff Scores sheet of count scores, following the export’s filters.
Each set’s picks arrive with every item code labelled.
SPSS export is on Professional+, which Research Team includes.
Not part of a MaxDiff yet: pictures as items, items carried forward from an earlier question, MaxDiff charts on dashboards or in report decks, and a share simulator or TURF. HB scores show on the Results tab; count scores show there and in the client portal.
Choosing
Both tell you what comes first. Ranking asks for an order; MaxDiff asks for trade-offs, a few items at a time.
Ranking gives an average rank and how often each item came first. MaxDiff gives each item a share of preference, out of 100 across the list, and groups items into tiers, so you can see which gaps are real. For bundles of features at price points, use Conjoint (CBC) (Research Team).
Build it
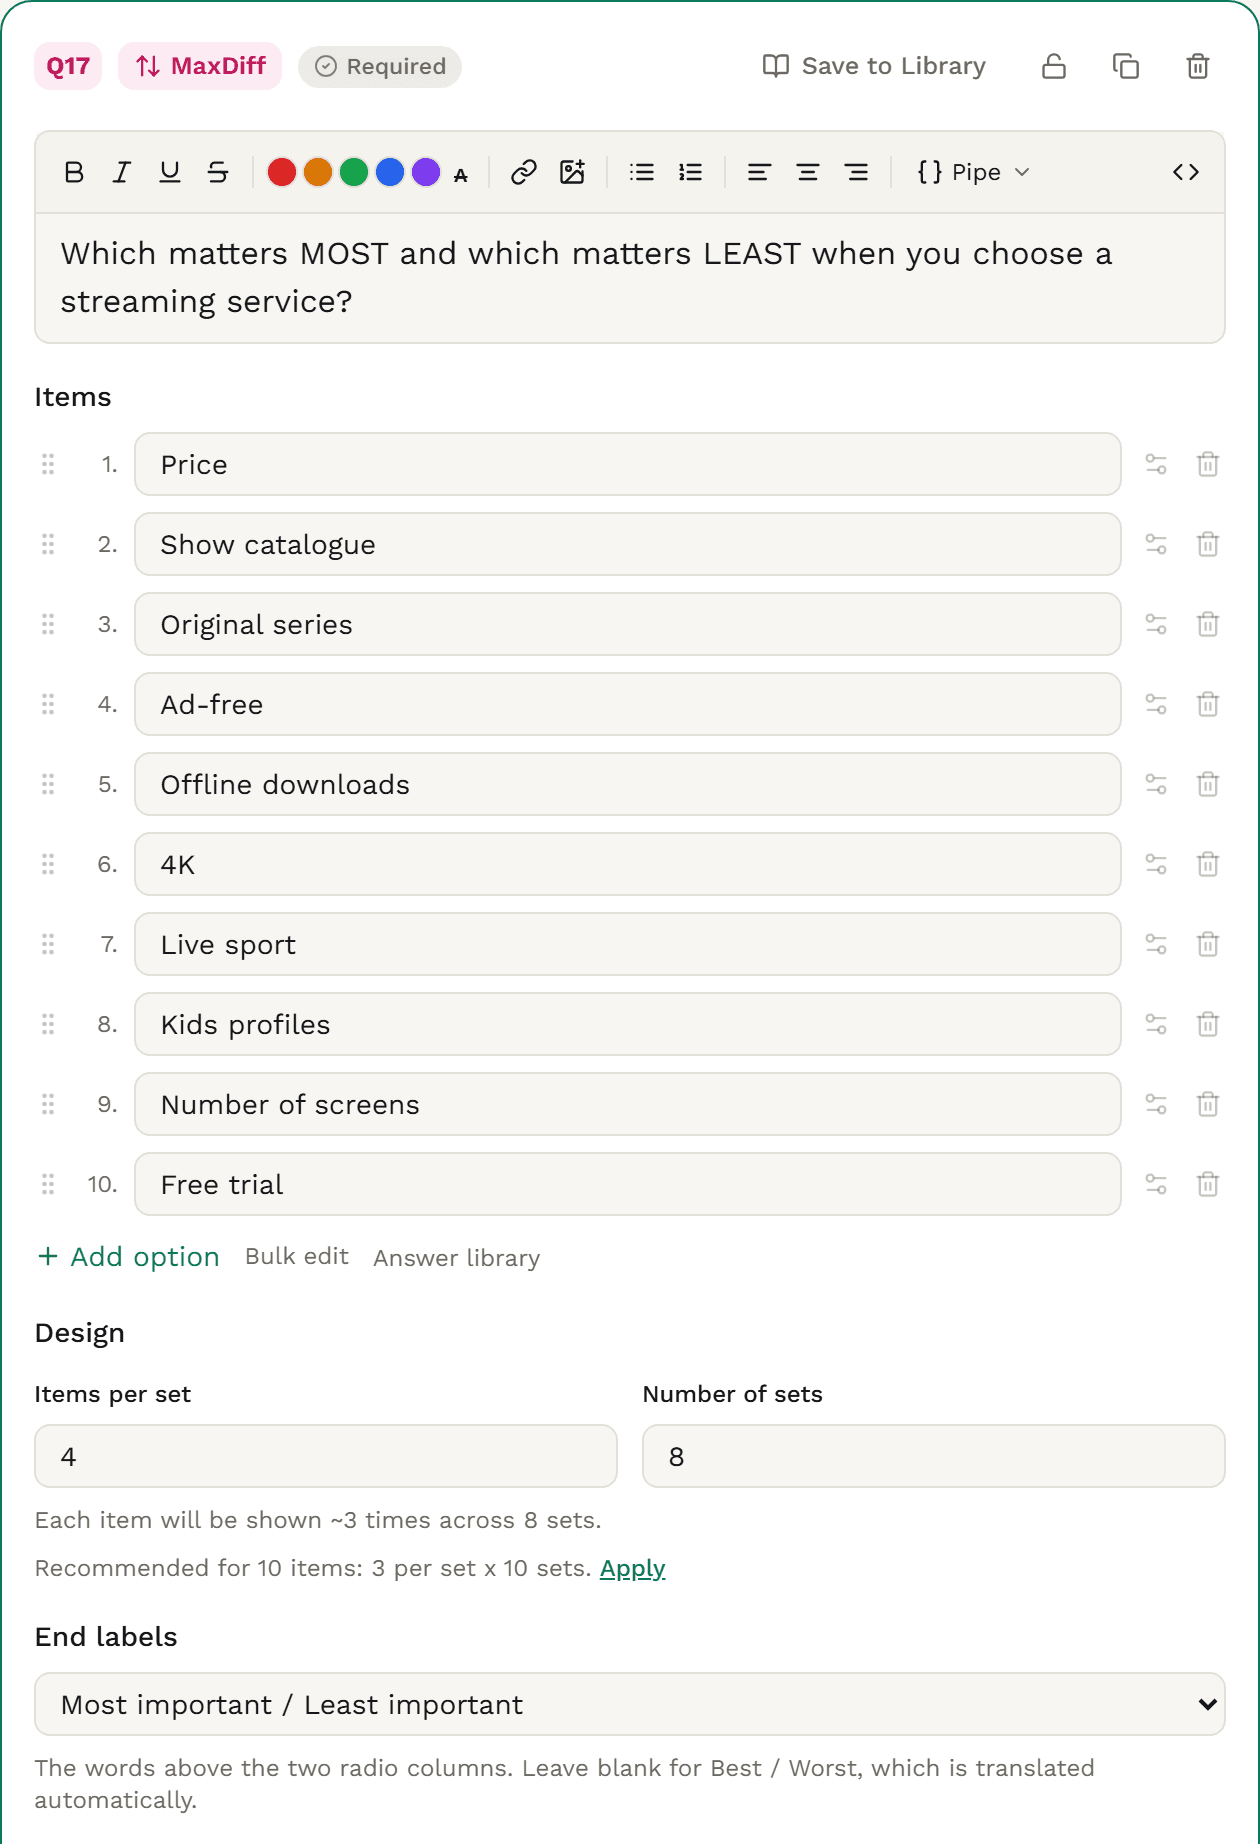
In the builder, add a question and choose MaxDiff (“Best / worst tradeoffs”) from the Ranking group. Ask both ends in the question, such as “Which matters MOST and which matters LEAST when you choose a streaming service?”
Type them under Items, or open Bulk edit and paste one per line. Keep them the same kind of thing, such as all features.
Under Design, choose Items per set and Number of sets. The hint tells you how often each item will be shown; aim for about 3 times. Change the list and the editor offers a recommended design you can apply.
Under End labels, pick a preset such as Most important / Least important, or pick Custom and set the Top label and Bottom label to match your question. They translate with the survey.
Tick Anchored (dual response) and each set ends by asking how many of its items actually matter, so you can tell which items clear the bar, not just which win.
Keep it required. Then show a follow-up when the MaxDiff’s best item is any of Price, or pipe it in: “Why does ${Q1.best} matter most?” Preview on a phone.
The data you get
Each set gets a pair of columns with the codes of the two picks. The HB export adds every respondent’s scores, the design file adds one row per item shown, and Excel and SPSS turn the codes back into item names.
| respondent_id | Q1_set1_bestSet 1, most important | Q1_set1_worstSet 1, least important | Q1_set2_bestSet 2, most important | Q1_set2_worstSet 2, least important | Q1_set3_bestSet 3, most important | Q1_set3_worstSet 3, least important | Q1_set4_bestSet 4, most important | Q1_set4_worstSet 4, least important | Q1_set5_bestSet 5, most important | Q1_set5_worstSet 5, least important | Q1_set6_bestSet 6, most important | Q1_set6_worstSet 6, least important | Q1_set7_bestSet 7, most important | Q1_set7_worstSet 7, least important | Q1_set8_bestSet 8, most important | Q1_set8_worstSet 8, least important |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 47762a85-0001-4000-8000-000000000001 | 2 | 10 | 8 | 9 | 3 | 9 | 8 | 6 | 2 | 5 | 3 | 4 | 8 | 9 | 9 | 7 |
| 47762a85-0002-4000-8000-000000000002 | 1 | 9 | 2 | 7 | 5 | 8 | 2 | 10 | 3 | 5 | 4 | 8 | 1 | 7 | 7 | 6 |
| 47762a85-0003-4000-8000-000000000003 | 4 | 8 | 3 | 5 | 2 | 7 | 6 | 5 | 1 | 10 | 7 | 9 | 2 | 4 | 2 | 5 |
| 47762a85-0004-4000-8000-000000000004 | 7 | 6 | 3 | 9 | 2 | 8 | 3 | 8 | 4 | 10 | 2 | 8 | 7 | 9 | 1 | 10 |
| 47762a85-0005-4000-8000-000000000005 | 2 | 8 | 5 | 10 | 4 | 2 | 4 | 9 | 1 | 8 | 5 | 9 | 10 | 4 | 4 | 6 |
| 47762a85-0006-4000-8000-000000000006 | 8 | 10 | 1 | 5 | 4 | 2 | 8 | 1 | 5 | 10 | 1 | 10 | 8 | 4 | 1 | 5 |
| 47762a85-0007-4000-8000-000000000007 | 5 | 8 | 3 | 7 | 1 | 4 | 1 | 9 | 5 | 10 | 10 | 6 | 5 | 8 | 5 | 4 |
| 47762a85-0008-4000-8000-000000000008 | 1 | 8 | 3 | 10 | 2 | 8 | 1 | 2 | 10 | 9 | 2 | 10 | 4 | 9 | 1 | 10 |
Trimmed to the question’s columns, two per set. Each cell holds an item code: 1 is Price, 7 is Live sport. The names under the headers are for reading here; the file holds the column names only. Every export also carries the standard respondent columns (status, source, timing and more).
| Question | respondent_id | version | set | position | item | label | best | worst | anchor |
|---|---|---|---|---|---|---|---|---|---|
| Q1 | 47762a85-0001-4000-8000-000000000001 | 1 | 1 | 1 | 2 | Show catalogue | 1 | 0 | (empty) |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 1 | 1 | 2 | 4 | Ad-free | 0 | 0 | (empty) |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 1 | 1 | 3 | 3 | Original series | 0 | 0 | (empty) |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 1 | 1 | 4 | 10 | Free trial | 0 | 1 | (empty) |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 1 | 2 | 1 | 9 | Number of screens | 0 | 1 | (empty) |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 1 | 2 | 2 | 6 | 4K | 0 | 0 | (empty) |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 1 | 2 | 3 | 8 | Kids profiles | 1 | 0 | (empty) |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 1 | 2 | 4 | 1 | Price | 0 | 0 | (empty) |
The export dialog’s MaxDiff design (long) format, a CSV, trimmed to the first two sets of one respondent. One row per item shown, with 1 marking the pick at each end. version numbers each respondent in the file and position is the item’s place in the set; an anchored MaxDiff fills anchor with all, some or none. It’s the layout to take to your own model, if you want one, in R, or Sawtooth after reshaping.
| respondent_id | iteration | share_1Price | util_1Price | share_2Show catalogue | util_2Show catalogue | share_10Free trial | util_10Free trial | rlh | flagged | removed | weight | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| d3000000-0000-4000-8000-5c0016000001 | 0 | 14.67 | 0.732 | 14.82 | 0.753 | … | 3.56 | -1.229 | 0.387 | 0 | 0 | 1 |
| d3000000-0000-4000-8000-5c0016000002 | 0 | 20.64 | 1.575 | 18.23 | 1.267 | … | 3.97 | -1.014 | 0.414 | 0 | 0 | 1 |
| d3000000-0000-4000-8000-5c0016000003 | 0 | 21.50 | 1.695 | 19.94 | 1.485 | … | 3.57 | -1.157 | 0.392 | 0 | 0 | 1 |
| d3000000-0000-4000-8000-5c0016000011 | 0 | 16.65 | 0.954 | 15.88 | 0.863 | … | 5.38 | -0.732 | 0.331 | 1 | 0 | 1 |
From Export scores on the HB card, as CSV, Excel or SPSS, trimmed and rounded here; the file keeps full precision. One row per respondent: each item’s share of preference (share_1 is Price, and one person’s shares add up to 100) and raw HB utility (util_1), then RLH, the close-to-random flag, whether they were removed from scores, and their weight (weighting is on Research Team). The fourth row is flagged: an RLH of 0.331, at or below this design’s cut-off of 0.34. Anyone removed from scores is listed with removed = 1 and blank scores.
The HB summary sheet in Excel
| item | mean_share | low_95 | high_95 | tier | tier_label | topk_chance | mean_utility | |
|---|---|---|---|---|---|---|---|---|
| Price | 17.0623 | 16.2214 | 17.8728 | 1 | Clearly on top | 1 | 1.1194 | … |
| Show catalogue | 15.4636 | 14.5585 | 16.3388 | 2 | Middle 1 | 1 | 0.9115 | … |
| Ad-free | 12.3675 | 11.5515 | 13.043 | 3 | Middle 2 | 0.932 | 0.511 | … |
| Offline downloads | 11.586 | 10.8824 | 12.2812 | 3 | Middle 2 | 0.068 | 0.2145 | … |
| … 5 more items | … | … | … | … | … | … | … | … |
| Free trial | 3.8527 | 3.4418 | 4.2749 | 8 | Least important | 0 | -1.126 | … |
The workbook’s HB summary sheet, trimmed: each item’s mean share, 95% range, tier, chance in top 3 (0 to 1) and mean utility, then its best, worst and shown counts where the dots are. A Notes sheet says how each number was made, including the cut-off: 0.34, from 200 simulated random respondents answering this design (pure chance is 0.29). In SPSS, each share and HB utility variable is labelled with its item, such as “Price: share of preference” and “Price: HB utility”. SPSS export is on Professional+, which Research Team includes.
Q1_set1_best and Q1_set1_worst through set 8, named after the question or your export tag. The names say best and worst whatever your end labels say.
Each cell is an item code. Excel’s Value Labels sheet and SPSS value labels turn every code back into the item’s name.
The MaxDiff design (long) export: every item each person saw, set by set, with their two picks marked. It’s the file a model needs, because the pick columns alone don’t say what else was on screen.
Each respondent’s share of preference and raw HB utility for every item, with their RLH, the close-to-random flag and whether they were removed. Excel adds a summary sheet and notes.
Download the count scores on the Results tab, best-minus-worst and ranked by item, as CSV or Excel, for the same respondents, filters and weights (Research Team) as the count card. See it below.
With an anchor, each set adds Q1_set1_anchor and so on, holding all, some or none.
Weighted exports carry a weight column, and the SPSS syntax sets WEIGHT BY weight. Weighting is on Research Team.
Charts & analysis
Hierarchical Bayes scores each person’s picks, then shows each item’s share of preference, out of 100 across the list, with a 95% likely range. Items the data can’t tell apart share a tier. Count scores stay as the quick view.
Which matters MOST and which matters LEAST when you choose a streaming service?Results · Preference scores (Hierarchical Bayes)
Research Team
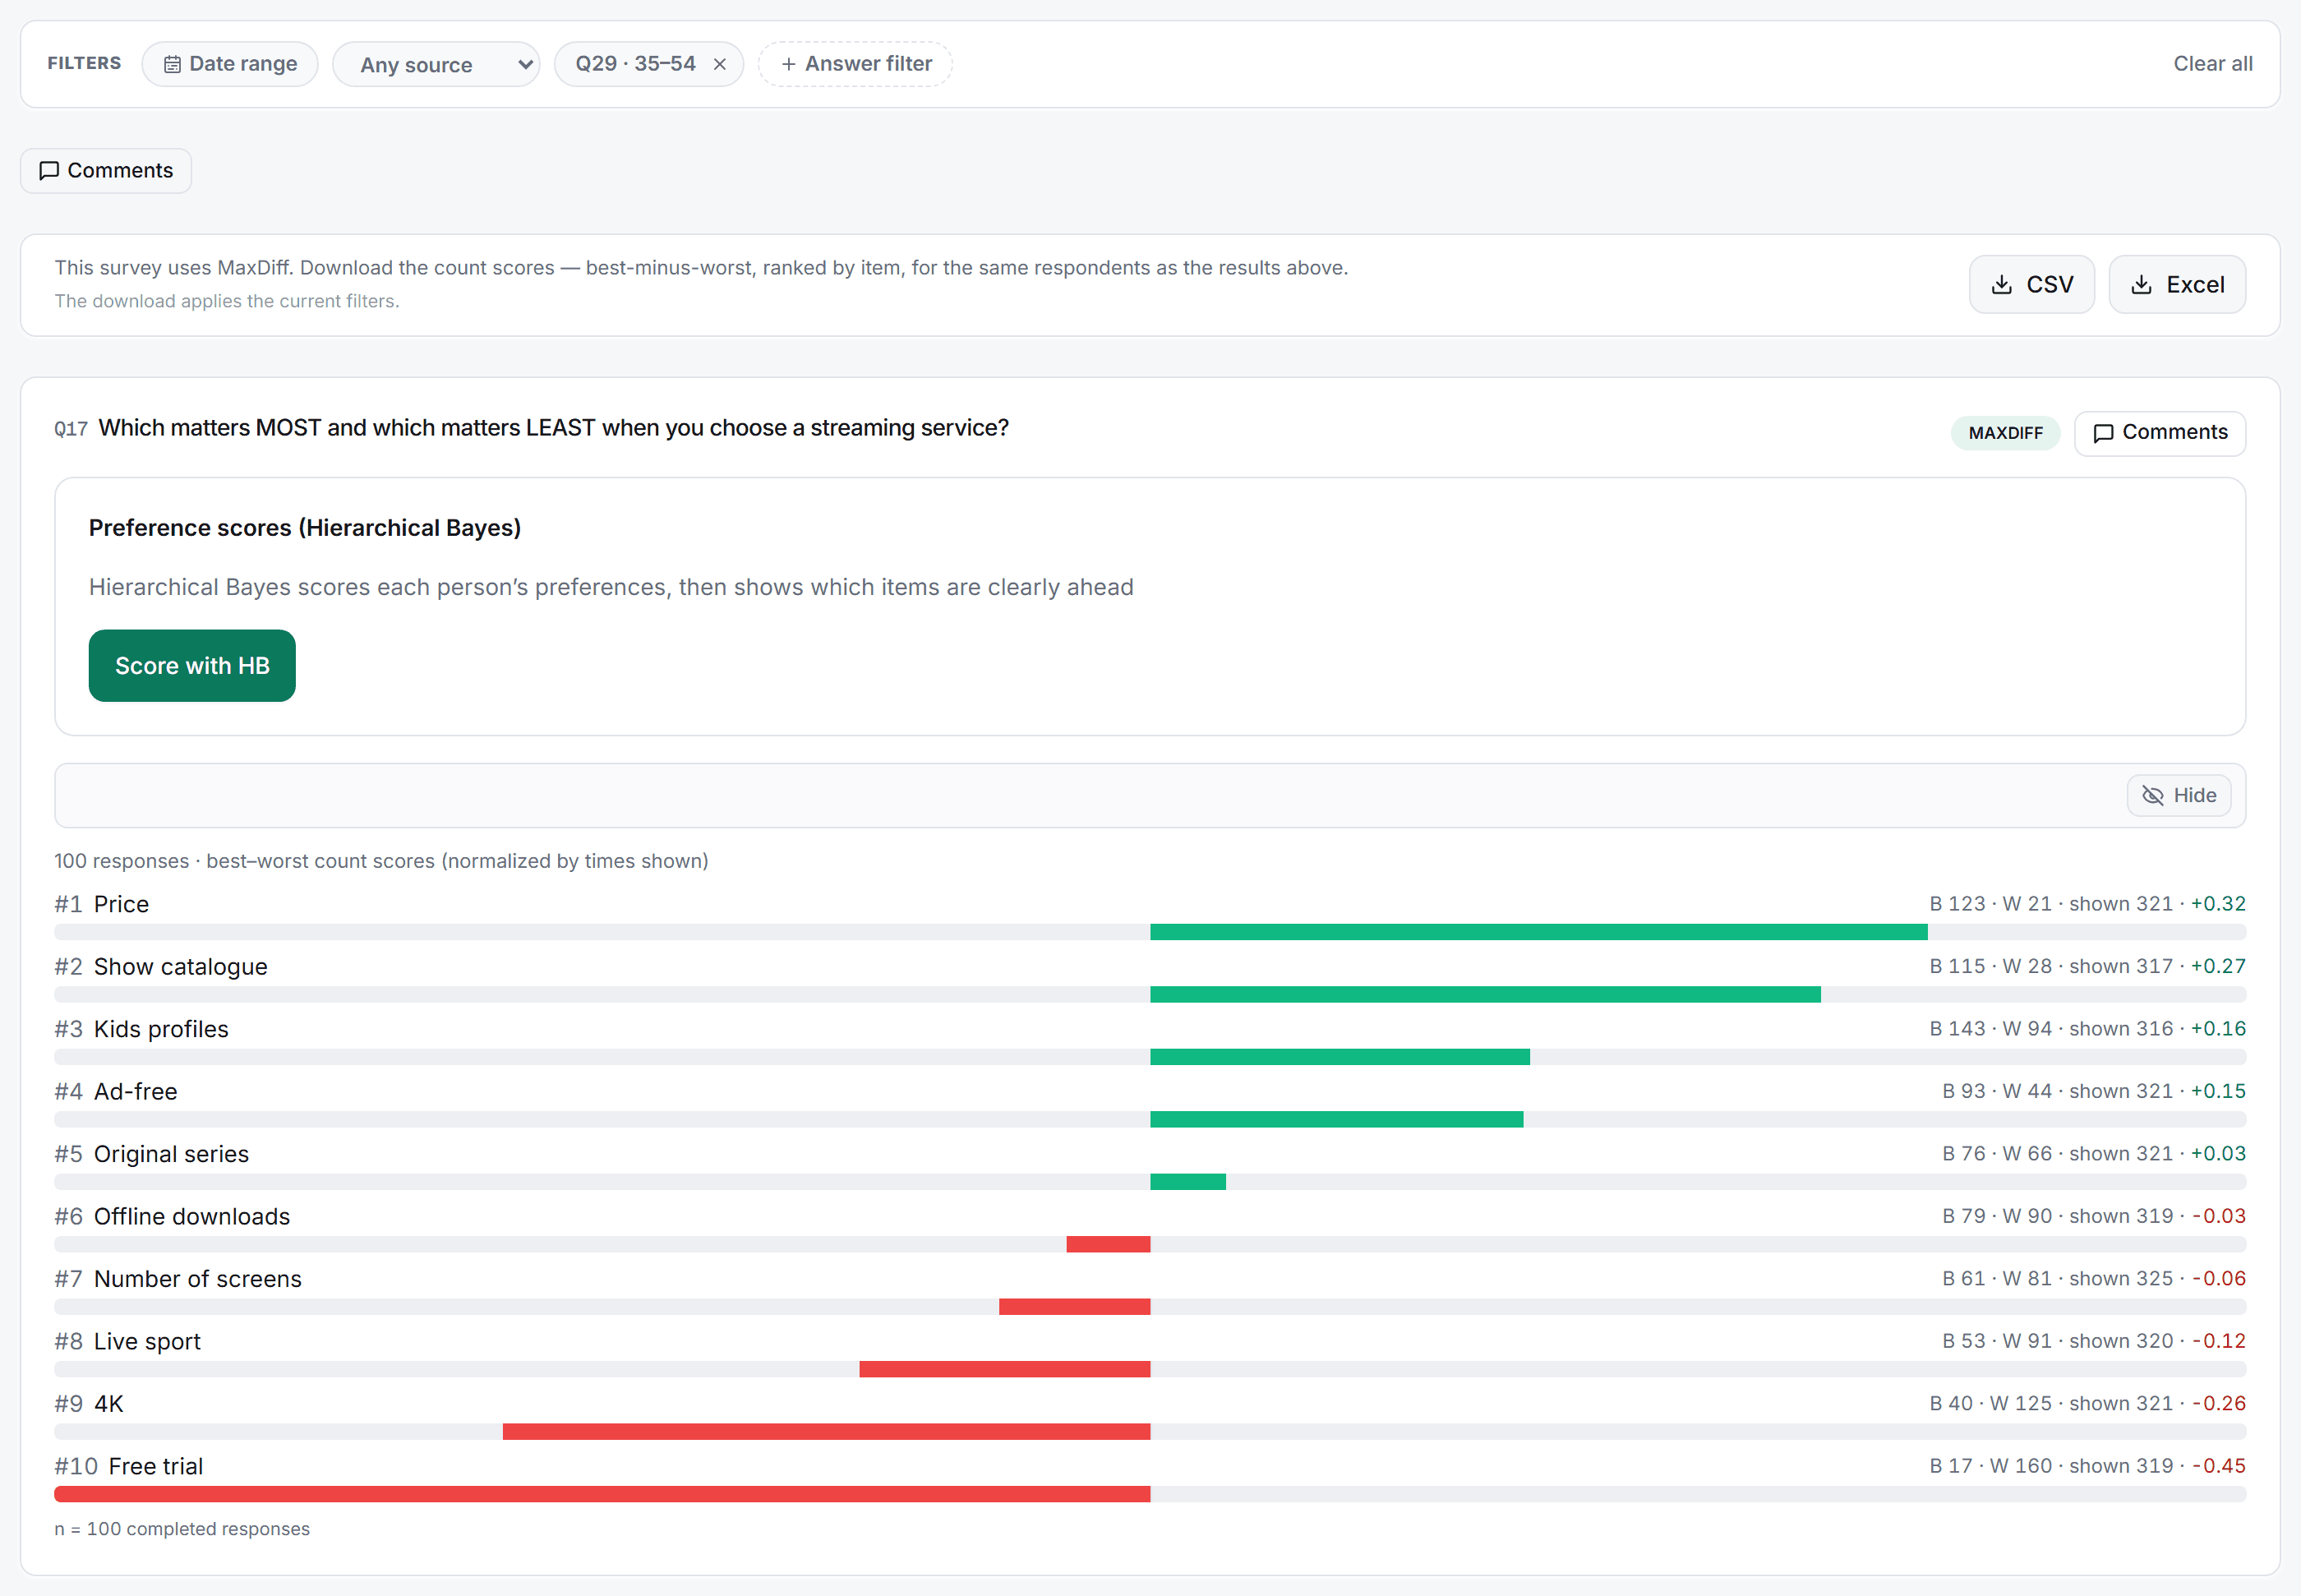
The quick view: count scoresResults · MaxDiff count card · count scores

Scores by ageResults filtered to each age group · count scores, with each item’s rank in that group
Research Team| Item | Totaln 300 | 18–34n 111 | 35–54n 100 | 55+n 89 |
|---|---|---|---|---|
| Price | +0.38 · #1 | +0.37 · #1 | +0.32 · #1 | +0.47 · #1 |
| Show catalogue | +0.32 · #2 | +0.31 · #2 | +0.27 · #2 | +0.39 · #2 |
| Ad-free | +0.18 · #3 | +0.12 · #5 | +0.15 · #4 | +0.26 · #3 |
| Original series | +0.08 · #4 | +0.17 · #4 | +0.03 · #5 | +0.02 · #5 |
| Offline downloads | +0.07 · #5 | +0.30 · #3 | -0.03 · #6 | -0.10 · #6 |
| Live sport | -0.07 · #6 | -0.13 · #6 | -0.12 · #8 | +0.05 · #4 |
| Number of screens | -0.15 · #7 | -0.23 · #8 | -0.06 · #7 | -0.16 · #7 |
| Kids profiles | -0.19 · #8 | -0.42 · #10 | +0.16 · #3 | -0.28 · #8 |
| 4K | -0.24 · #9 | -0.16 · #7 | -0.26 · #9 | -0.30 · #9 |
| Free trial | -0.39 · #10 | -0.35 · #9 | -0.45 · #10 | -0.36 · #10 |
Filter the Results tab by age and the list re-ranks for that group. Price leads in every group. Kids profiles is #3 for 35 to 54s (+0.16) and near the bottom elsewhere (-0.42 for 18 to 34s, -0.28 for 55+). Offline downloads scores +0.30 with 18 to 34s against -0.10 with 55+. These are count scores, and differences between groups aren’t tested. For one group at a time, you can also re-run HB on the filtered base.
Each HB run checks every respondent’s fit (RLH) against a cut-off simulated from 200 random respondents answering your design. Flagged people stay in until you choose: see who, preview the scores without them, or remove them and re-fit. Restore brings them back.
Weight the survey and each pick and each showing counts by the person’s weight, on the Results tab and in the count-scores file. HB averages each person’s shares with the same weights.
Filter Results by another question, such as age or plan type, and the count scores re-rank for that group. Re-run HB to score that group too. The count-scores file follows the same filter.
With an anchor, each item also gets its % above threshold: the share of anchored answers that put it above the “actually matters” line, so you can see which items clear it, not just which win.
The HB scores are built in. To fit a model of your own as well, export the MaxDiff design (long) file and use it in R, or Sawtooth after reshaping: one row per item shown, with both picks marked.
Data exportsThe count-scores fileDownload the count scores on the Results tab · CSV or Excel · the same respondents, filters and weights (Research Team) as the count card
Research Team| Question | Rank | Item | Times shown | Best picks | Worst picks | Count score |
|---|---|---|---|---|---|---|
| Q1 | 1 | Price | 964 | 430 | 62 | 0.382 |
| Q1 | 2 | Show catalogue | 951 | 389 | 84 | 0.321 |
| Q1 | 3 | Ad-free | 970 | 285 | 115 | 0.175 |
| Q1 | 4 | Original series | 965 | 235 | 159 | 0.079 |
| Q1 | 5 | Offline downloads | 961 | 305 | 236 | 0.072 |
| Q1 | 6 | Live sport | 960 | 177 | 245 | -0.071 |
| Q1 | 7 | Number of screens | 957 | 143 | 291 | -0.155 |
| Q1 | 8 | Kids profiles | 959 | 246 | 424 | -0.186 |
| Q1 | 9 | 4K | 956 | 118 | 343 | -0.235 |
| Q1 | 10 | Free trial | 957 | 72 | 441 | -0.386 |
The counts are whole numbers here: Price was shown 964 times, with 430 best and 62 worst picks, for (430 − 62) / 964. Across the 300 respondents, each item was shown 951 to 970 times: 3 or 4 times per person.
How Surveti compares
| Capability | Surveti | SurveyMonkey | Qualtrics | Alchemer | QuestionPro |
|---|---|---|---|---|---|
| MaxDiff on the free or entry plan | paidResearch Team plan | paid1, 3Optional add-on, per study | paid7A separate purchase | paid19Full Access licence only | paid24, 30Research Edition |
| Published price for MaxDiff | yes$449/mo, or $349/mo yearly | unclear3Price didn’t load | no7Ask your account executive | yes20Full Access $275/mo | no30Research Suite: contact sales |
| Balanced design, documented | yesPer person: exposure within one, pairs spread, order shuffled | yes130 balanced versions | partial8Conditions listed, no method named | partial18Pseudo-balanced; not every item shown | unclear25, 31Items “showed randomly” |
| Design you can download | yesMaxDiff design (long) export: every set each person saw | yes1Experimental design as CSV | unclear11Not mentioned | partial18Raw data, one row per set | unclear27Not covered |
| Anchored MaxDiff | yesAll, some or none after each set | unclear1Not mentioned | yes8, 9 | unclear18Not addressed | yes28Labelled beta |
| Edit after launch without resetting the analysis | partialWording and items, yes; keep the set design fixed | no1MaxDiff questions are locked | no9Any saved change resets it | unclearNot covered | unclearNot covered |
| Accessibility statement covering MaxDiff | yesThis page: named sets, focus moves to the new set | unclear6MaxDiff not mentioned | no15On the not-accessible list | unclear22Not mentioned | unclearNone found |
| Model-based scores (EB, HB or logit) | yesPer-respondent HB, with ranges and tiers (Research Team) | yes1, 4Empirical Bayes | yes8HB, written in STAN | unclear18A count score only | partial26, 27Aggregate, from best and worst shares |
| Fit statistic (RLH) per respondent | yesRLH against a cut-off simulated for your design, on by default | unclear1, 2No fit statistic documented | unclear8No fit statistic mentioned | unclear18No fit statistic documented | unclear27No fit statistic documented |
| Scores by segment | yesResults filter, one group at a time | yes1, 2Filters on every MaxDiff chart | yes12, 13Up to 12 segments | partial18Advice only | yes27Data filter |
| Crosstabs and significance tests on MaxDiff | noUse the Results filter | unclear1Not mentioned | no10“Crosstabs are not available” | no18Not in crosstab reports | unclear27Not covered |
| Choice-level data per respondent | yesOne row per item shown | partial1, 2Layout not described | unclear11, 14Not mentioned | yes18One row per set shown | yes270 / 1 / 2 sheet |
| SPSS export of MaxDiff data | paidPer-set picks, labelled · Professional+ | partial1, 2Layout not described | unclear11CSV and TSV only documented | no18“Does not export via the SPSS Export” | yes27, 31 |
Partial means partly built in or possible only with a documented workaround; paid means built in on paid tiers, licences or add-ons only; unclear means the vendor’s docs don’t settle it. Sawtooth Software, Typeform and Conjointly were also reviewed. Sawtooth, the MaxDiff specialist, has a free Discover tier up to 50 respondents per survey, scores with HB, and offers a “Design & choices” download for its desktop tools. Typeform has no MaxDiff question. Conjointly includes MaxDiff from $2,895 per team per year.
Items the data can’t tell apart share a tier, worked out from the HB draws rather than by eyeballing ranges. None of the tools we reviewed documents a tier summary, and Qualtrics shows no ranges at all.
Every HB run flags respondents who answered close to random, against a cut-off simulated for your design, and keeps them in until you decide. SurveyMonkey, Qualtrics, Alchemer and QuestionPro document no fit statistic for MaxDiff.
MaxDiff, with HB scoring, is on the Research Team plan: $449 a month, or $349 a month billed yearly, for 10 seats. Of the four tools we compared, only Alchemer publishes a price for MaxDiff.
Each person gets their own balanced sets. When the sets have room for the whole list, everyone sees every item, here 3 or 4 times each, so no score rests on a few people.
Export every set each person saw, with both picks marked, in the MaxDiff design (long) format, for R, or Sawtooth after reshaping.
Reword the question or an item on a live survey and the answers and scores carry on; a reworded item asks you to confirm it first. SurveyMonkey locks MaxDiff questions, and Qualtrics resets the analysis on any saved change.
Each set is a named group, every pick says its item and its end, and focus moves to the new set. Qualtrics lists its MaxDiff matrix as not accessible.
Turn on the dual-response anchor and each set asks how many of the items matter. QuestionPro labels its anchored MaxDiff beta; SurveyMonkey and Alchemer don’t document one.
When to use it
“Which matters MOST and which matters LEAST when you choose a streaming service?” 10 items · Most important / Least important · 4 per set · 8 sets
Accessibility
A set is a group called “Set 2 of 8”. When the set changes, focus moves to its name, so a screen reader starts reading the new items.
Each pick is named for its end and its item, such as “Most important: Price”, in the survey’s language.
Tab to an end, then use the arrow keys to move and pick. The pick for the other end of a picked item is skipped.
Every pick has a 44px tap area by default and a clear focus ring in your survey’s theme, light or dark.
Use it in
Template
“Which of these features is MOST and LEAST important to you?” 6 features, 3 per set across 6 sets, next to a ranking question.
Solution
Prioritise the roadmap, then ask why the top pick matters with a piped follow-up.
Solution
Rank benefits or claims, weight (Research Team) to your targets, and see the scores for one group at a time.
Example
“Which matters MOST and which matters LEAST when you choose a streaming service?” 10 features, four per set, eight sets.
Surveti fits a Hierarchical Bayes model to each person’s picks, then turns their scores into shares of preference with Sawtooth’s probability-rescaled method, so the items add up to 100. Results shows each item’s average share, a 95% likely range, its chance of a top-3 place and its tier. In the example, Price leads at 17.1, likely between 16.2 and 17.9. For a quick view, each item also gets a count score: most-important picks minus least-important picks, divided by times shown, from −1 to +1. Price scores +0.38. With weighting on (Research Team), both use each person’s weight.
Yes. Per-respondent Hierarchical Bayes, on Research Team. Once the Results base has 50 respondents, choose Score with HB. It runs in the background and can take a few minutes. Runs are manual: when new responses arrive, the card says how many and offers Re-run. Each run follows the Results filter and weighting (Research Team). To fit your own model as well, export the MaxDiff design (long) file: one row per item each person saw, with both picks marked, for R, or Sawtooth after reshaping.
Aim for each item to be shown about 3 times. A set holds 2 to 6 items, and you can use up to 30 sets. The editor suggests a design for your list and shows how often each item will appear. The example uses 10 items, 4 per set and 8 sets, so each person sees every item 3 or 4 times.
Yes. Filter the Results tab by another question, such as age, and the count scores re-rank for that group; the count-scores file follows the same filter. You can re-run HB for that group too. One group shows at a time, and differences between groups aren’t tested.
Two columns per set, such as Q1_set1_best and Q1_set1_worst, holding item codes, labelled in Excel and SPSS (Professional+). The MaxDiff design (long) file adds every set each person saw, and the count-scores file has the count scores, best-minus-worst, ranked by item. The HB export gives each respondent’s share and raw HB utility for every item, with their RLH and flag, as CSV, Excel or SPSS. Answers are checked against the sets each person was served before they’re saved.
Yes. Set the two end labels to match your question, such as most and least important, or most and least appealing. They go into the translation sheet with the rest of the survey. “Set 2 of 8”, the “1/8 completed” count, Previous and Next come translated in six languages.
Research Team, at $449 a month or $349 a month billed yearly, alongside conjoint and the other advanced research types. It includes SPSS export and weighting.