LiveResearch Team
Attributes and levels
Name each feature and its levels, such as Price at $39, $49 and $59 a week. Add as many as the study needs.
Conjoint question · Matrix
Find out what people will trade for what. Respondents pick between whole products built from features and prices, and you get part-worths for every level, the importance of each feature, a simulator to test new products, and a holdout check on how well it all predicts.

Live demo
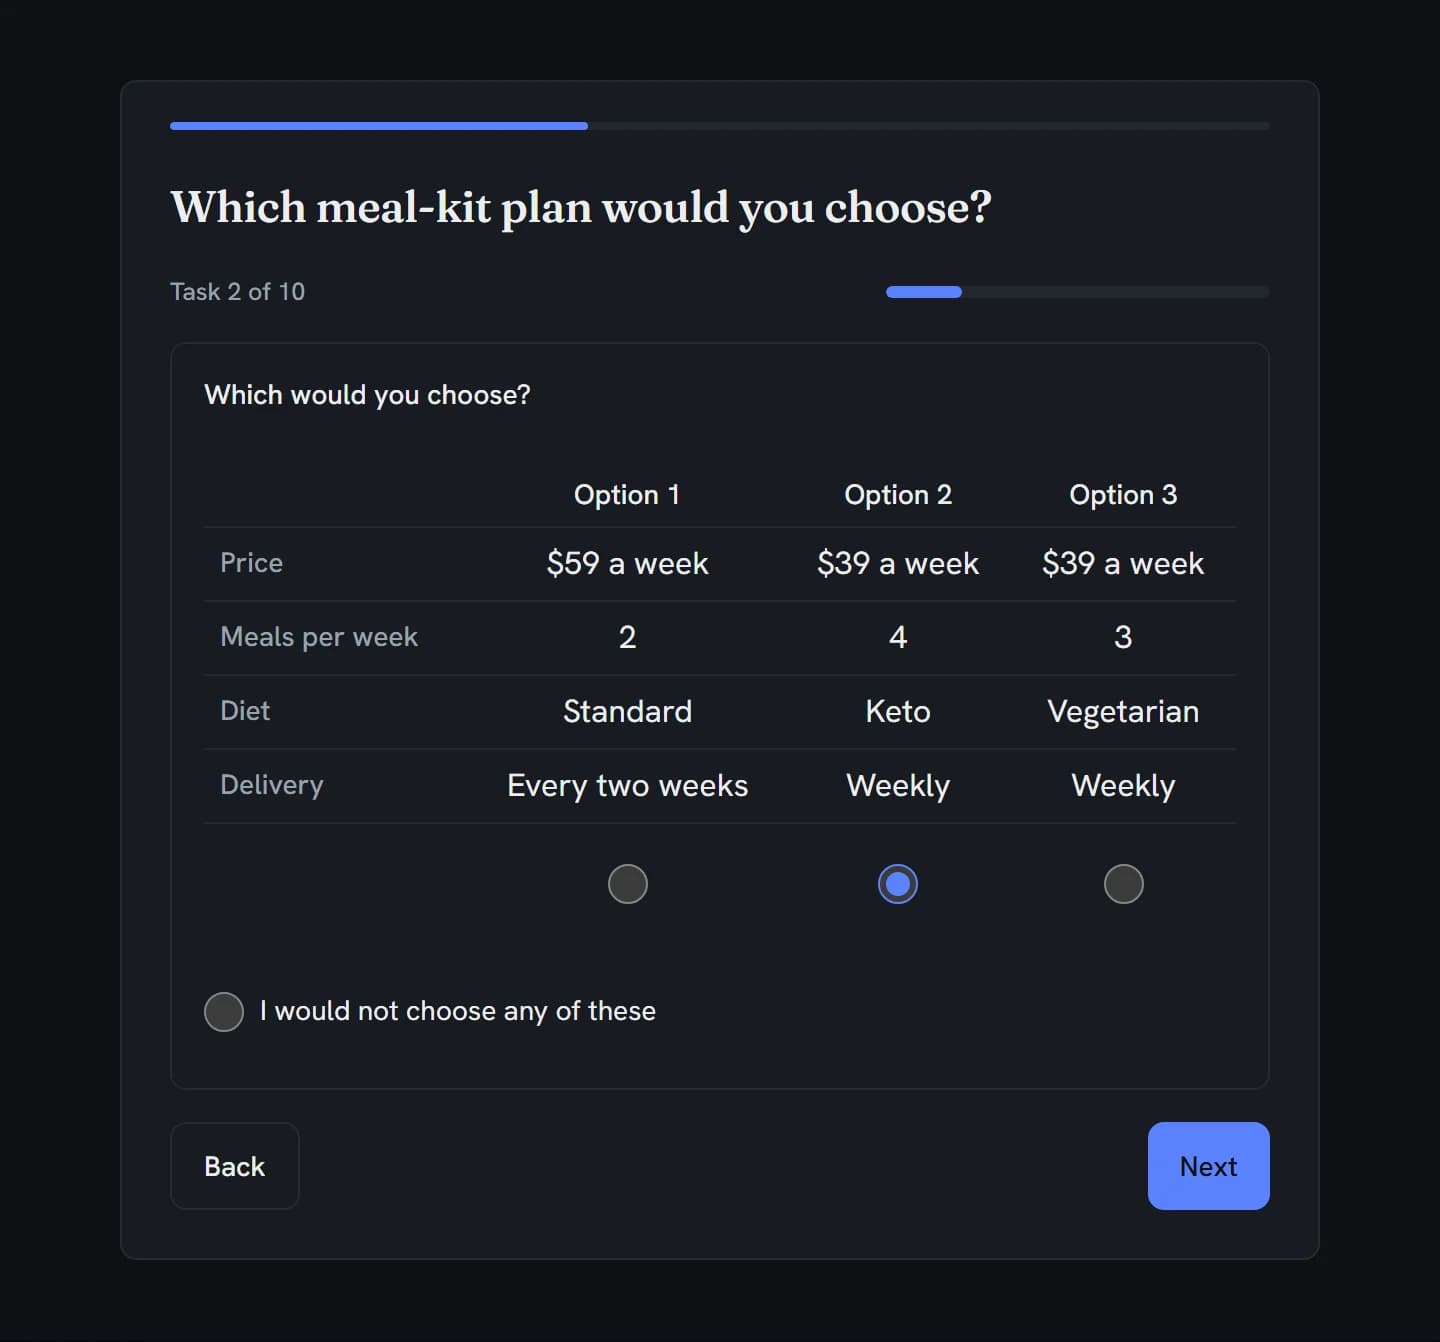
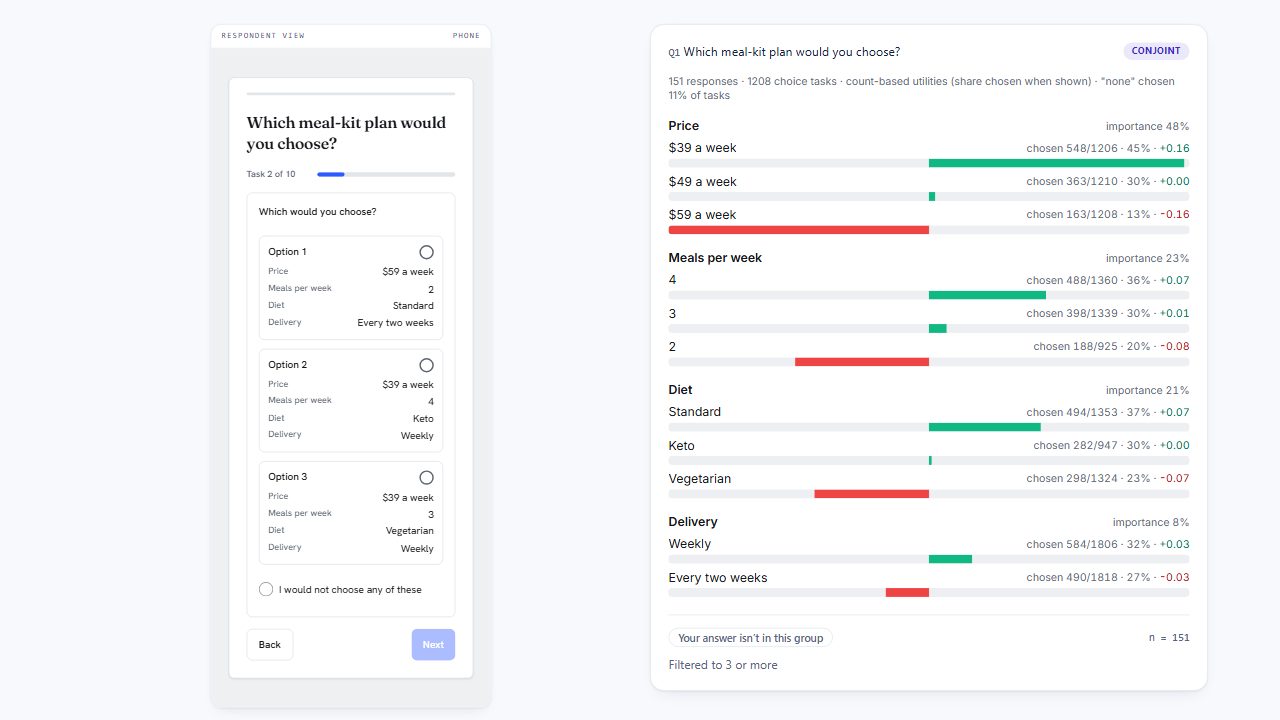
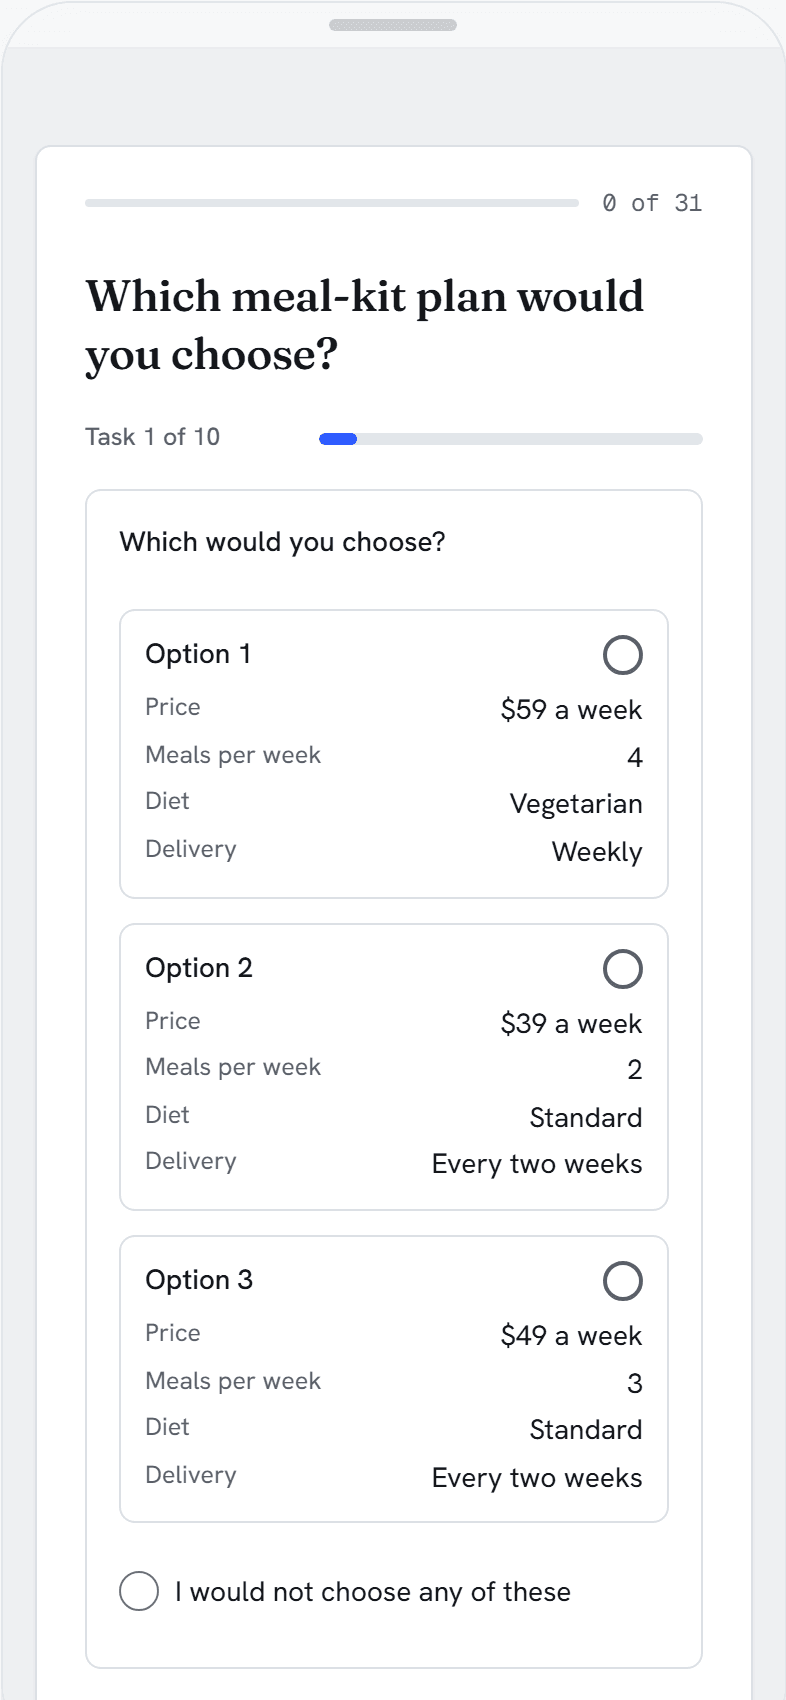
This is the question your respondents get, one task at a time. Choose the plan you’d buy, or none of them, and the count card beside it updates with your answers in it.
Which meal-kit plan would you choose?
Task 1 of 10
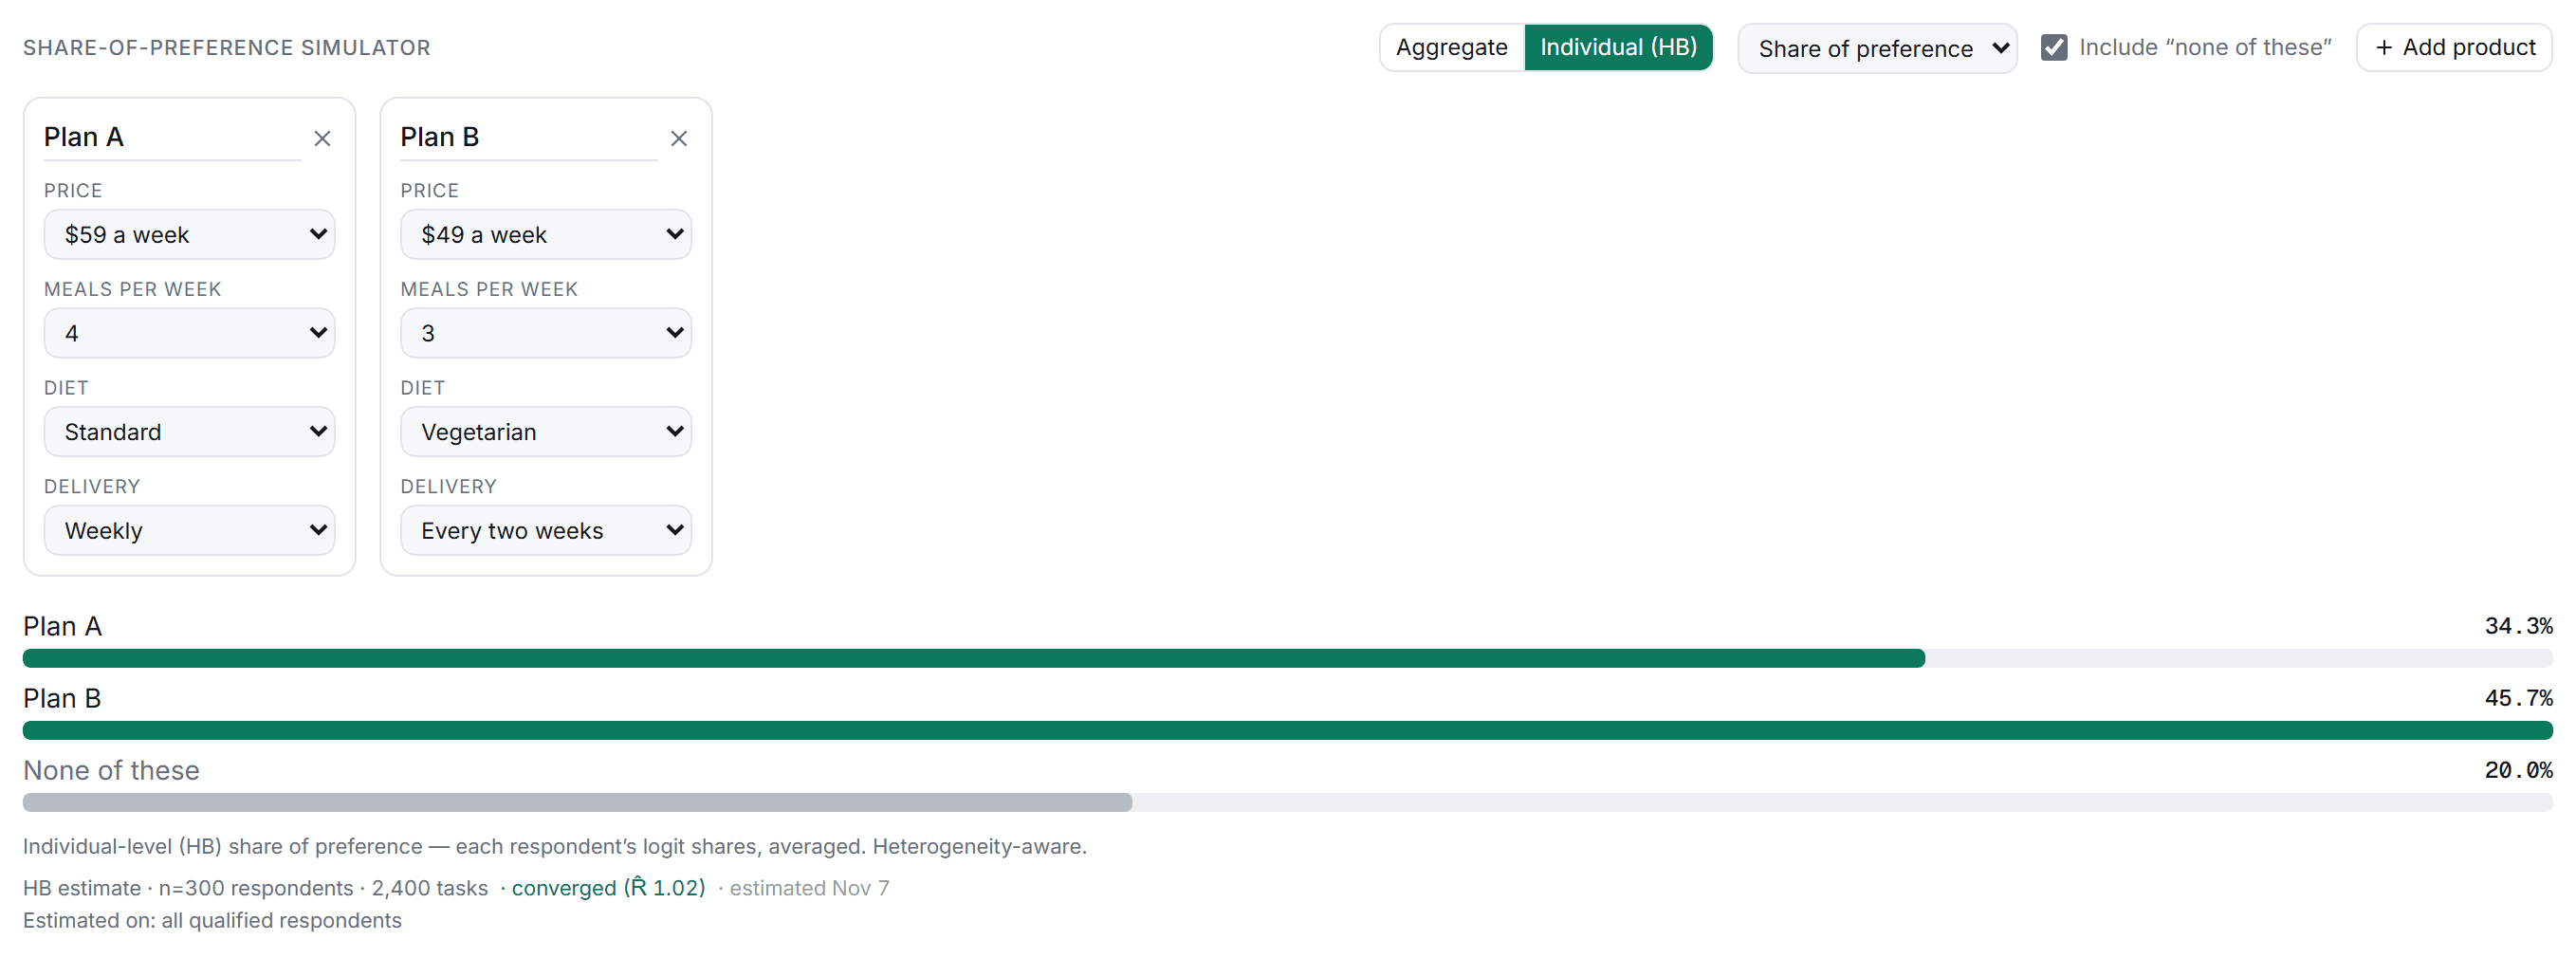
The share-of-preference simulator scores each plan with every respondent’s own part-worths and averages the result. Change a level and the shares move.
Share of preference: each person’s logit shares, averaged. HB run on these 300 respondents (All respondents). A what-if of relative preference, not a market forecast.
In action
Every feature
Level-balanced tasks for each respondent (a prohibition loosens it) or a design you upload, a choice screen that works on a phone, and an analysis that goes from counts to part-worths, individual-level estimates and a simulator, checked against holdouts.
Name each feature and its levels, such as Price at $39, $49 and $59 a week. Add as many as the study needs.
A new conjoint saves with two example attributes you rename, and launch waits until there are at least two attributes, each with two or more levels.
Set the number of tasks (8 by default), 2 to 6 cards per task, and whether people can choose none of them.
Up to three validation tasks that everyone sees, mixed in among the others and left out of the estimate.
Never first, and never back to back as long as there are at least as many tasks as holdouts.
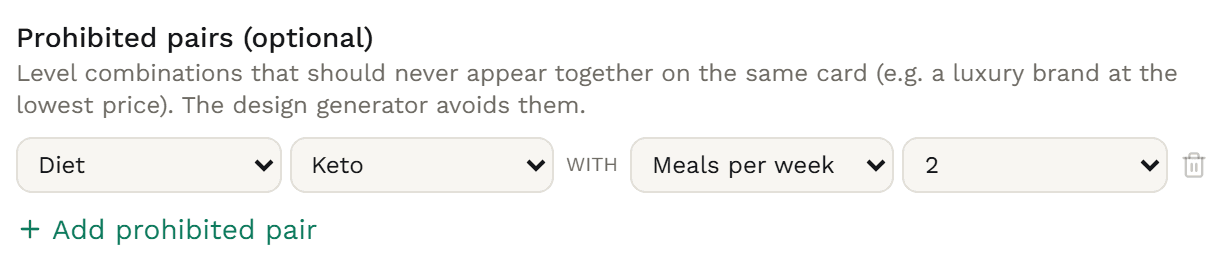
Rule out levels that can’t appear on the same card, such as Keto with only 2 meals.
Each prohibition makes the design a little less even.
The editor shows how often each level is shown and how often pairs of levels appear together, before you launch.
Upload a versioned design as CSV, with a template to start from. Each respondent gets one version, and a file with bad rows isn’t applied: the editor lists up to 10 problems.
“Task 3 of 10”, a progress bar, and Next once a choice is made. Holdouts look like any other task.
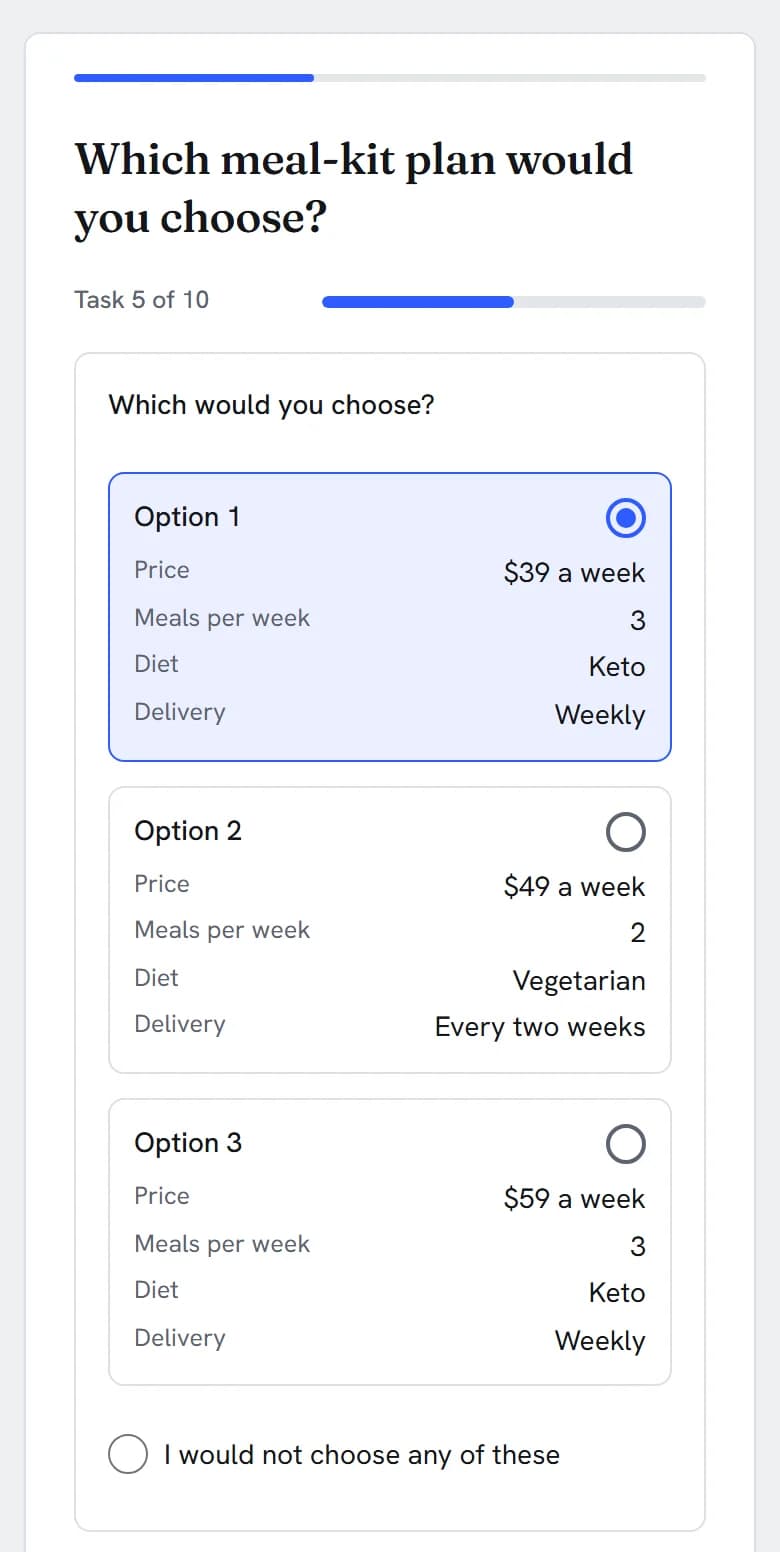
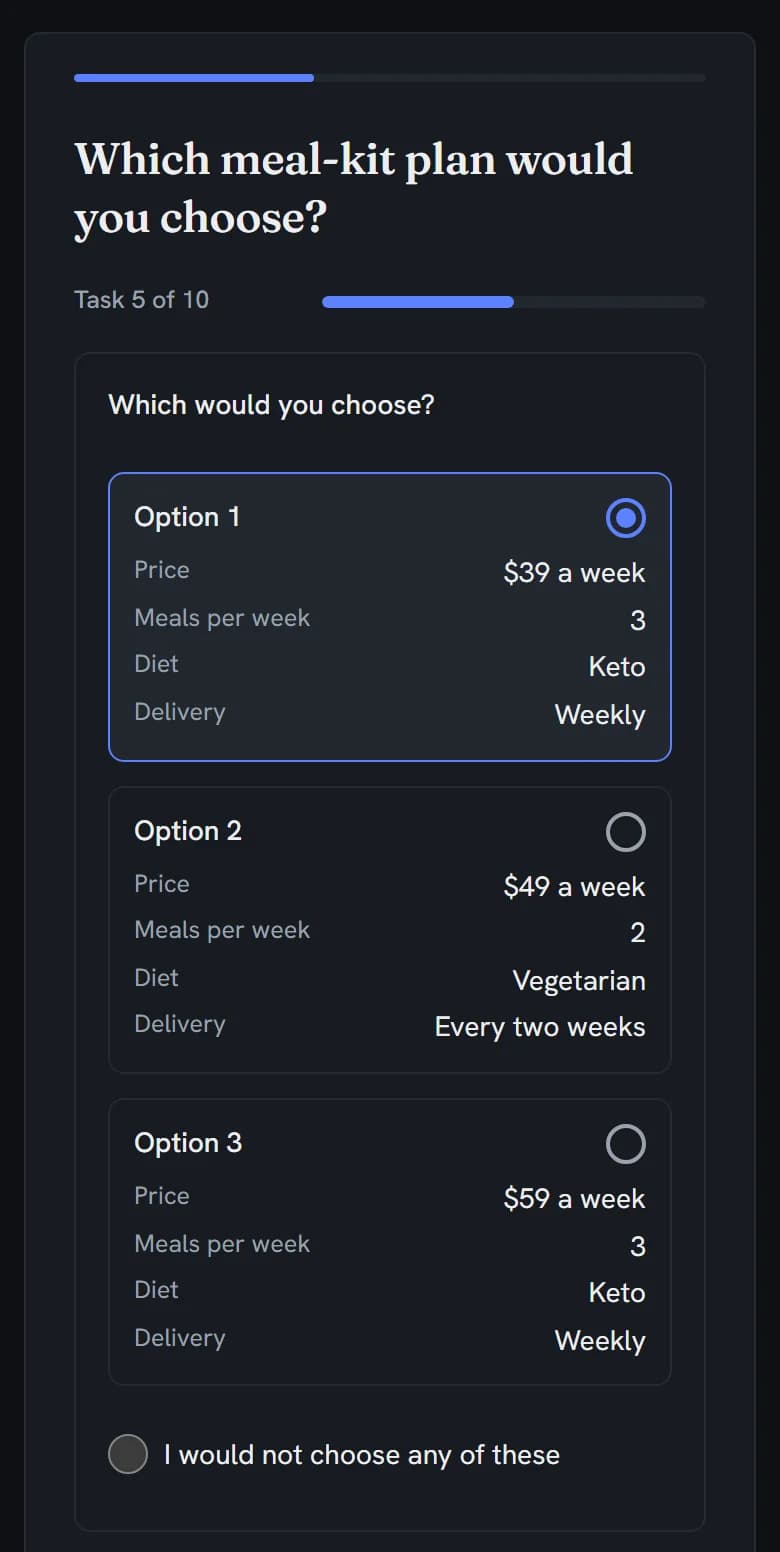
A side-by-side table on wider screens, and stacked cards with every level listed on phones.
Each person’s tasks come from a seed tied to them. The server rebuilds that design and checks every answer the survey sends against it, card for card and with the same holdouts for everyone, before it’s saved.
Back returns to the task before, with the choice still marked.
Attributes and levels go into the translation sheet with the rest of the survey. “Which would you choose?”, “Task 3 of 10”, the none option, Back and Next are available in six languages. Translations are for display only, so the analysis still lines up across languages.
Native radios on every screen: one per option in the table, and a whole card as the radio on phones. Every option is at least 44px tall by default, with a focus ring.
Tables, cards and choices follow the survey’s theme and dark mode.
How often each level was chosen when shown, each attribute’s importance from those counts, and the none share. The same card shows in the client portal.
An aggregate logit model gives each attribute’s importance, the model fit, and every level a part-worth with its standard error.
Choose Run HB analysis and Hierarchical Bayes estimates each respondent’s part-worths and importances in the background, with a convergence check. Re-run estimate runs it again with the Draws and Burn-in you set.
Build up to 8 products and see their shares of preference from the logit model, or from each person’s part-worths (HB) by share of preference or first choice, with or without none.
A what-if of relative preference, not a market forecast.
Results shows how often each model predicts the holdout choices against chance, the mean RLH, and how many respondents fit below chance. Each respondent’s RLH is in the utilities workbook.
Filter Results by another question and the logit part-worths, importances and the aggregate simulator are refit for that group. HB runs on that group when you choose Run HB on this base, or Run HB analysis if there’s no estimate yet.
One group at a time; differences aren’t tested.
One column holds each person’s choice for every task as a card position from 0 or none, base tasks first and then the holdouts, in the main CSV, Excel and JSON export.
In the export dialog: one row per attribute of every card each person saw, with the version, the task and the holdouts marked, and whether that card or none was chosen.
An Excel workbook from the Results tab with two sheets: Utilities (aggregate), each level’s part-worth, standard error and importance, and HB per respondent, each respondent’s part-worths, None and RLH, keyed by respondent ID.
The choices arrive as one text variable alongside the rest of the survey.
SPSS export is on Professional+, which Research Team includes.
Not part of a conjoint yet: pictures in place of level text, a price-per-utility calculation (price is a level like any other), a follow-up “would you really buy it?” question after each task, saving simulator setups between visits, and conjoint charts on dashboards or in report decks. Part-worths and the simulator are on the Results tab; the count card also shows in the client portal.
Choosing
Both make people choose. MaxDiff ranks a list of separate items; conjoint prices the features of one product against each other.
A common pairing: MaxDiff first to find the few features that matter, then conjoint to price them. MaxDiff gives count scores per item, and HB shares of preference; conjoint gives part-worths per level, importance per feature and a simulator.
Build it
In the builder, add a question and choose Conjoint (CBC) (“Choice-based tradeoffs”) from the Matrix group. It starts with two example attributes you can rename, so it works from the first preview.
Under Attributes & Levels, name each feature and its levels, such as Price with $39, $49 and $59 a week. Use Add attribute and Add level as you go. You need at least two attributes, each with two or more levels, before you can launch.
Choose the Number of tasks (8 is the default), Cards per task (2 to 6, default 3) and up to three Holdout tasks. Keep Include a “none of these” option on if people could walk away.
Under Prohibited pairs, choose Add prohibited pair for levels that can’t appear together, such as Keto with 2 meals. Then check Design quality for how often each level is shown and how often pairs of levels appear together.
Use Upload design (CSV) with a version, task and card on each row and a column per attribute; Template gives you one to fill in. Each respondent gets one version, and the server checks each answer against that version before it’s saved.
Preview on a phone, launch, and open Results. Part-worths appear as answers arrive; Run HB analysis estimates each person’s part-worths in the background, and Re-run estimate runs it again with more draws or burn-in when you need to.

The data you get
The main export keeps each person’s choices in one column. The design file lists every card each person saw, and the utilities workbook holds the part-worths, for the whole sample and for each respondent.
| respondent_id | Q1Choice per task, base tasks then holdouts |
|---|---|
| 47762a85-0001-4000-8000-000000000001 | 0; 2; 0; 2; 1; 1; none; 1; 1; 1 |
| 47762a85-0002-4000-8000-000000000002 | 0; 0; 0; none; 0; 0; 2; 0; 1; none |
| 47762a85-0003-4000-8000-000000000003 | 0; 0; 1; 0; 0; 2; 1; 0; 0; 0 |
| 47762a85-0004-4000-8000-000000000004 | 0; 0; 0; 1; none; 0; 2; none; 0; 0 |
| 47762a85-0005-4000-8000-000000000005 | none; 2; none; 0; 2; 1; 2; 2; 1; 2 |
| 47762a85-0006-4000-8000-000000000006 | 1; none; 2; 0; 1; 1; none; 0; 0; none |
| 47762a85-0007-4000-8000-000000000007 | 0; 2; 2; 2; 1; 2; 2; 1; 0; none |
| 47762a85-0008-4000-8000-000000000008 | 2; 0; 1; 0; 0; 1; 2; 2; 0; 0 |
Trimmed to the conjoint’s column. Each Q1 cell lists the 10 choices in the order the tasks are stored: the 8 regular tasks, then the 2 holdouts. 0 is the first card, and none is “I would not choose any of these”. The cards shown are in the design file, not here. Every export also carries the standard respondent columns (status, source, timing and more).
| Question | respondent_id | iteration | version | task | holdout | card | attribute | level | chosen | none_chosen |
|---|---|---|---|---|---|---|---|---|---|---|
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 1 | Diet | Standard | 1 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 1 | Price | $49 a week | 1 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 1 | Delivery | Every two weeks | 1 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 1 | Meals per week | 3 | 1 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 2 | Diet | Vegetarian | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 2 | Price | $49 a week | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 2 | Delivery | Every two weeks | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 2 | Meals per week | 3 | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 3 | Diet | Vegetarian | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 3 | Price | $59 a week | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 3 | Delivery | Weekly | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 1 | 0 | 3 | Meals per week | 3 | 0 | 0 |
| … | … | … | … | … | … | … | … | … | … | … |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 1 | Diet | Keto | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 1 | Price | $39 a week | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 1 | Delivery | Every two weeks | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 1 | Meals per week | 4 | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 2 | Diet | Vegetarian | 1 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 2 | Price | $39 a week | 1 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 2 | Delivery | Weekly | 1 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 2 | Meals per week | 3 | 1 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 3 | Diet | Vegetarian | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 3 | Price | $59 a week | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 3 | Delivery | Every two weeks | 0 | 0 |
| Q1 | 47762a85-0001-4000-8000-000000000001 | 0 | (empty) | 9 | 1 | 3 | Meals per week | 3 | 0 | 0 |
The export dialog’s Conjoint design (long) format, a CSV, trimmed to one respondent’s first task and first holdout. One row per attribute of each card shown: chosen is 1 on the rows of the card picked, and none_chosen is 1 on every row of a task the person passed on. card counts from 1 here, where the choice column counts from 0. holdout marks the validation tasks, numbered after the base tasks, and version is filled when you upload a design. Each card’s attributes come in the order the answer is stored, which can differ from the editor’s.
| attribute | level | utility | se | importance |
|---|---|---|---|---|
| Price | $49 a week | 0.094 | 0.039 | 54.04 |
| Price | $59 a week | -0.923 | 0.046 | 54.04 |
| Price | $39 a week | 0.828 | 0.039 | 54.04 |
| Meals per week | 3 | 0.139 | 0.039 | 25.06 |
| Meals per week | 2 | -0.475 | 0.048 | 25.06 |
| Meals per week | 4 | 0.336 | 0.039 | 25.06 |
| Diet | Standard | 0.166 | 0.039 | 12.01 |
| Diet | Vegetarian | 0.057 | 0.039 | 12.01 |
| Diet | Keto | -0.223 | 0.044 | 12.01 |
| Delivery | Every two weeks | -0.144 | 0.027 | 8.89 |
| Delivery | Weekly | 0.144 | 0.027 | 8.89 |
| None | None | -0.640 | 0.064 | (empty) |
From Download utilities on the Results tab: the Utilities (aggregate) sheet, rounded here (the file keeps full precision). It opens with a line naming its base and n, then gives each level’s part-worth (utility), its standard error (se) and its attribute’s importance, for the Results filters you have on. Part-worths sum to zero within each attribute, and importance is the attribute’s range as a % of all the ranges. The last row is the “none of these” constant, which has no importance.
| respondent_id | iteration | Diet: Standard | Diet: Vegetarian | Diet: Keto | Price: $49 a week | Price: $59 a week | Price: $39 a week | … | None | rlh |
|---|---|---|---|---|---|---|---|---|---|---|
| d3000000-0000-4000-8000-5c0017000001 | 0 | 0.744 | -0.231 | -0.513 | -0.029 | -1.049 | 1.078 | … | -0.564 | 0.315 |
| d3000000-0000-4000-8000-5c0017000002 | 0 | 0.682 | 0.056 | -0.738 | 0.061 | -1.214 | 1.153 | … | -0.525 | 0.475 |
| d3000000-0000-4000-8000-5c0017000003 | 0 | 0.828 | 0.269 | -1.097 | -0.104 | -1.064 | 1.167 | … | -0.644 | 0.433 |
| d3000000-0000-4000-8000-5c0017000004 | 0 | 0.389 | -0.052 | -0.337 | -0.131 | -1.187 | 1.318 | … | -0.445 | 0.460 |
| d3000000-0000-4000-8000-5c0017000005 | 0 | 0.495 | -0.287 | -0.208 | 0.011 | -1.242 | 1.232 | … | -0.462 | 0.505 |
From Download utilities: the HB per respondent sheet, one row per respondent on the HB estimate for the Results base you have on, keyed by respondent ID so it joins the main export. One column per level, with the attributes as the estimate lists them, then None and the person’s fit (rlh); iteration numbers a looped pass. Trimmed and rounded here; the file has every level at full precision. These are the same first respondents as the CSV tab, in the same order: this sample comes from the real HB estimate on the example survey, while the CSV, Excel and design-file samples were exported with stand-in IDs, so the IDs differ on this page. In your own downloads they’re the same.
Q1 holds every choice in stored order, base tasks then holdouts, as a card position from 0 or none. It’s named after the question or your export tag.
The Conjoint design (long) export: every card each person saw, task by task and one row per attribute, with the choice marked and the holdouts flagged. A model needs it, because the choice column alone doesn’t say what was on screen.
The aggregate part-worths with their standard errors and each attribute’s importance, and each respondent’s HB part-worths and fit (RLH), keyed by respondent ID.
Download utilities follows the Results filters: the aggregate sheet is refit for the group you’re viewing, and the HB sheet holds the HB estimate on that same base. If the HB panel shows another base’s estimate, the HB sheet is a note to run one on this base.
Charts & analysis
The Results tab fits a logit model to every choice and shows each level’s part-worth with its standard error; the chart below draws ± 1.96 standard errors around it. Choose Run HB analysis and Hierarchical Bayes adds part-worths for each respondent, which the simulator can run on, and the holdout tasks show how well each model predicts choices it never saw.
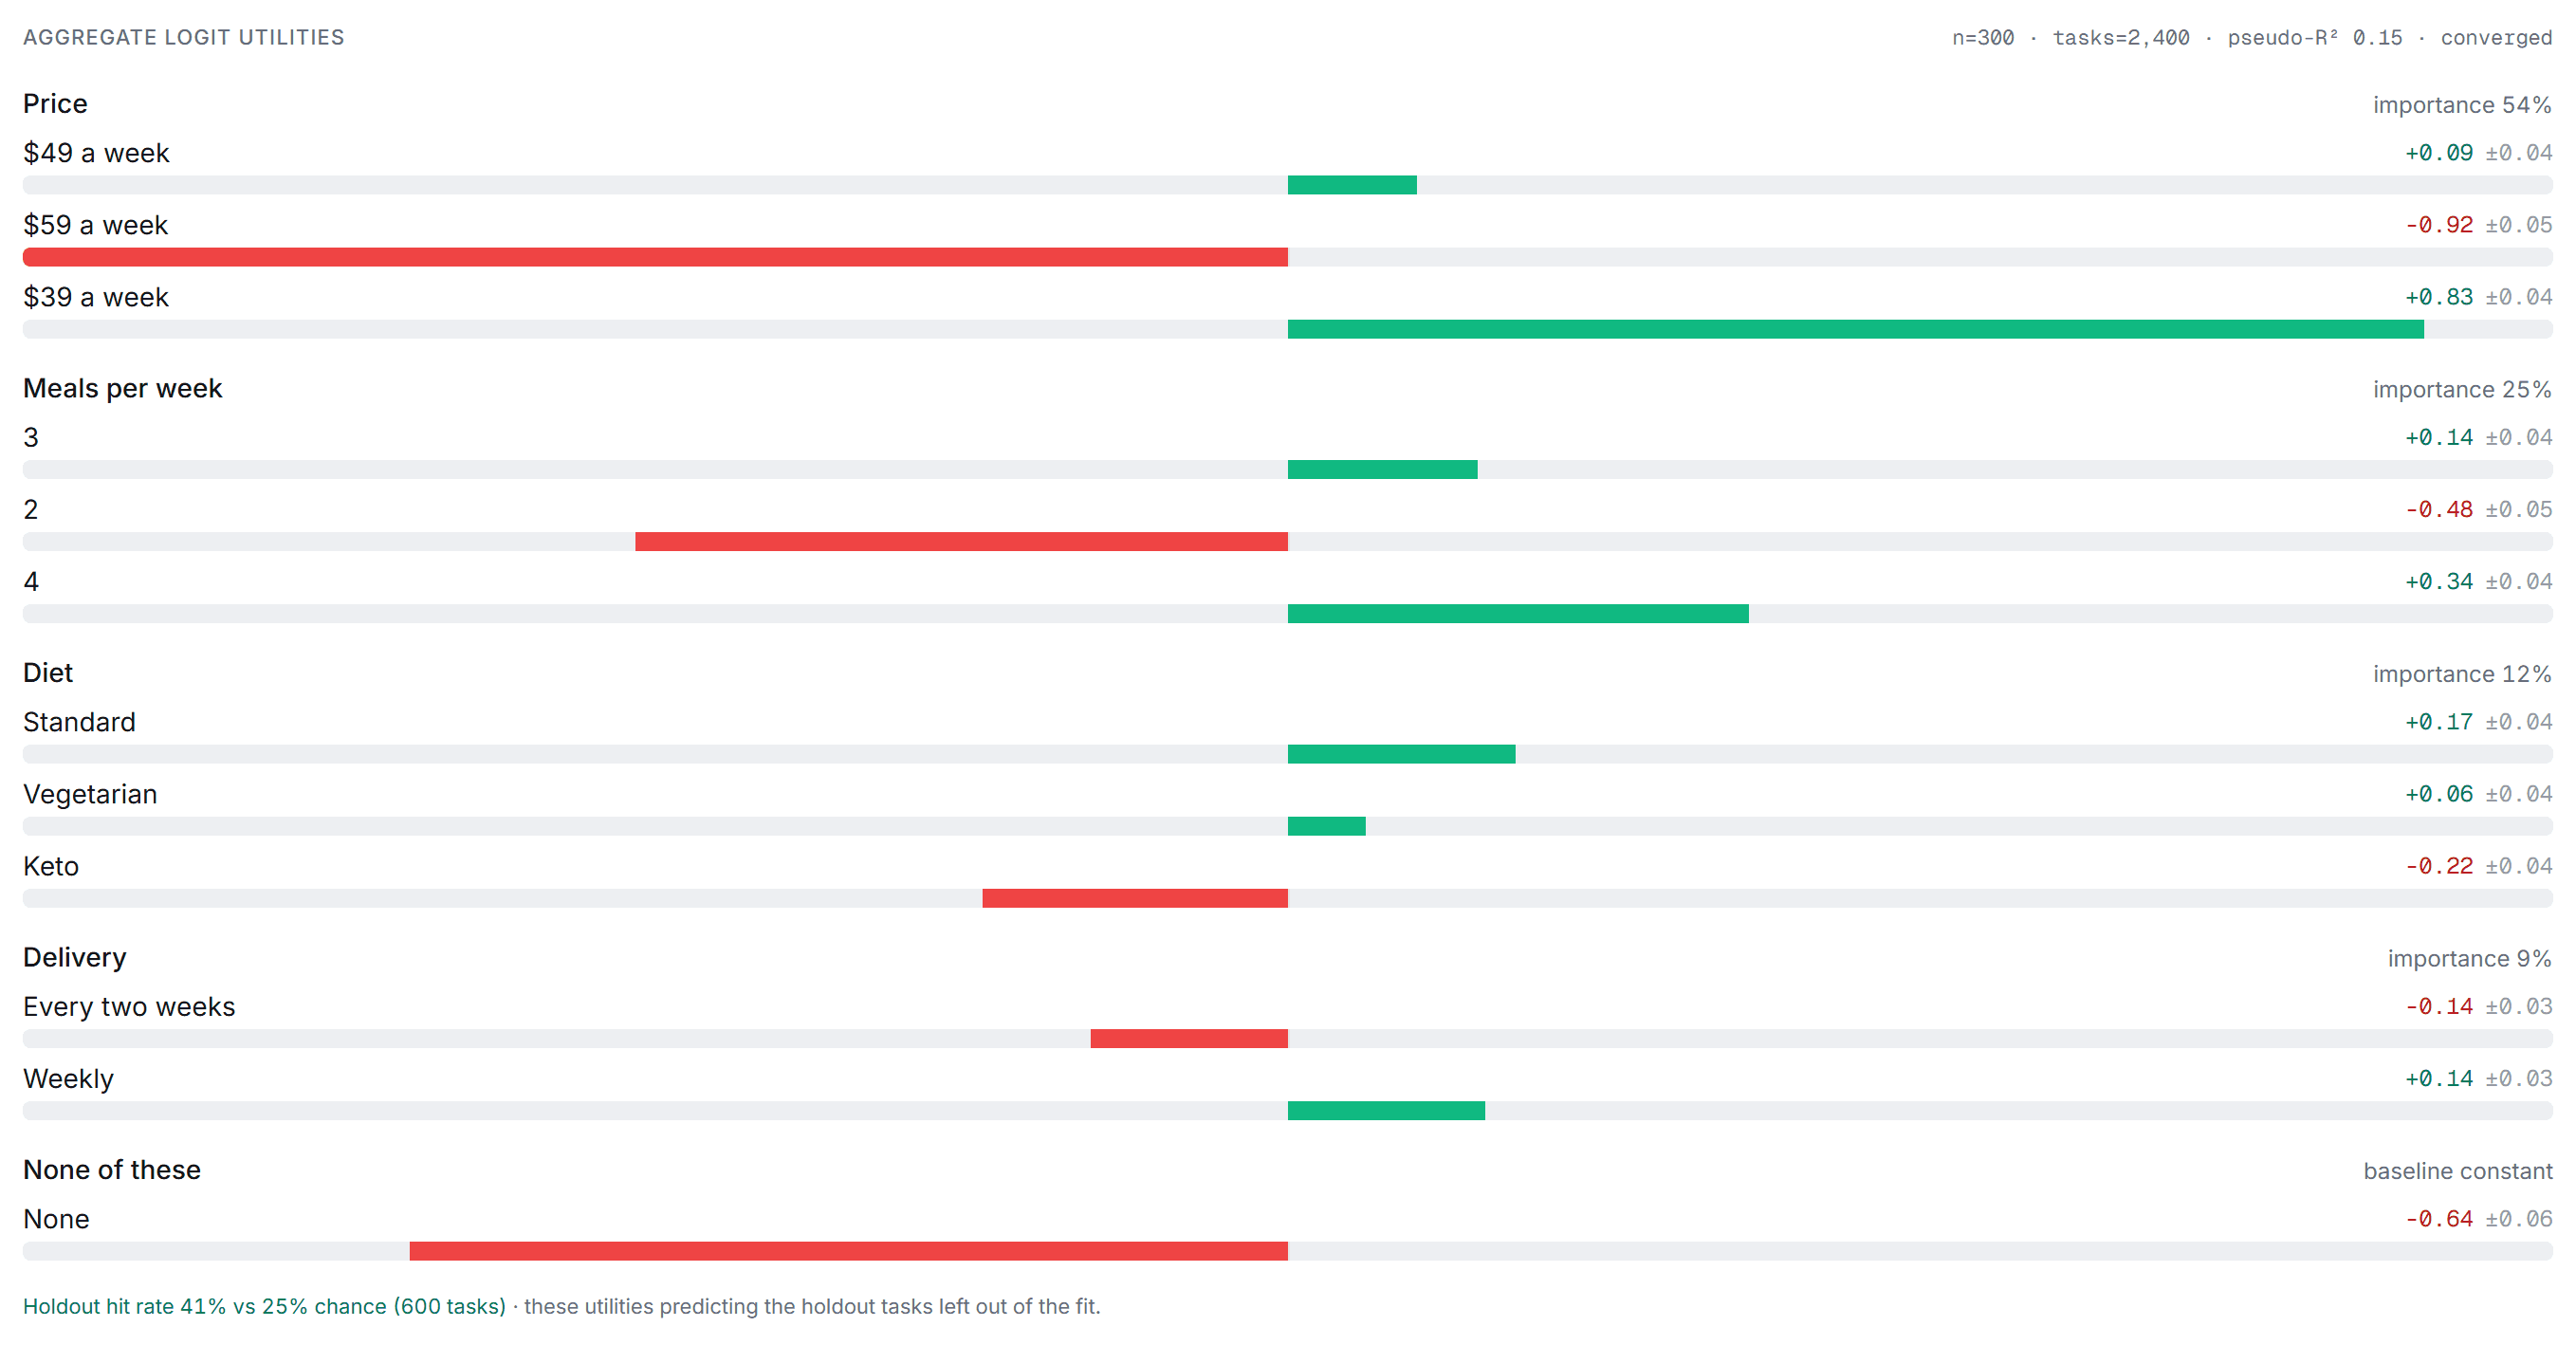
Which meal-kit plan would you choose?Results · Aggregate logit utilities · n=300 · tasks=2,400 · pseudo-R² 0.15 · converged
Part-worths sum to zero within each attribute; the bar is the part-worth ± 1.96 standard errors. $39 a week is 0.83 (0.75 to 0.90) and $59 a week is -0.92 (-1.01 to -0.83). Four meals is 0.34 against -0.48 for two. The none constant is -0.64.
Attribute importanceAggregate logit · each attribute’s part-worth range as a % of the total
Price accounts for 54% of the spread in preference, then Meals per week (25%), Diet (12%) and Delivery (9%).
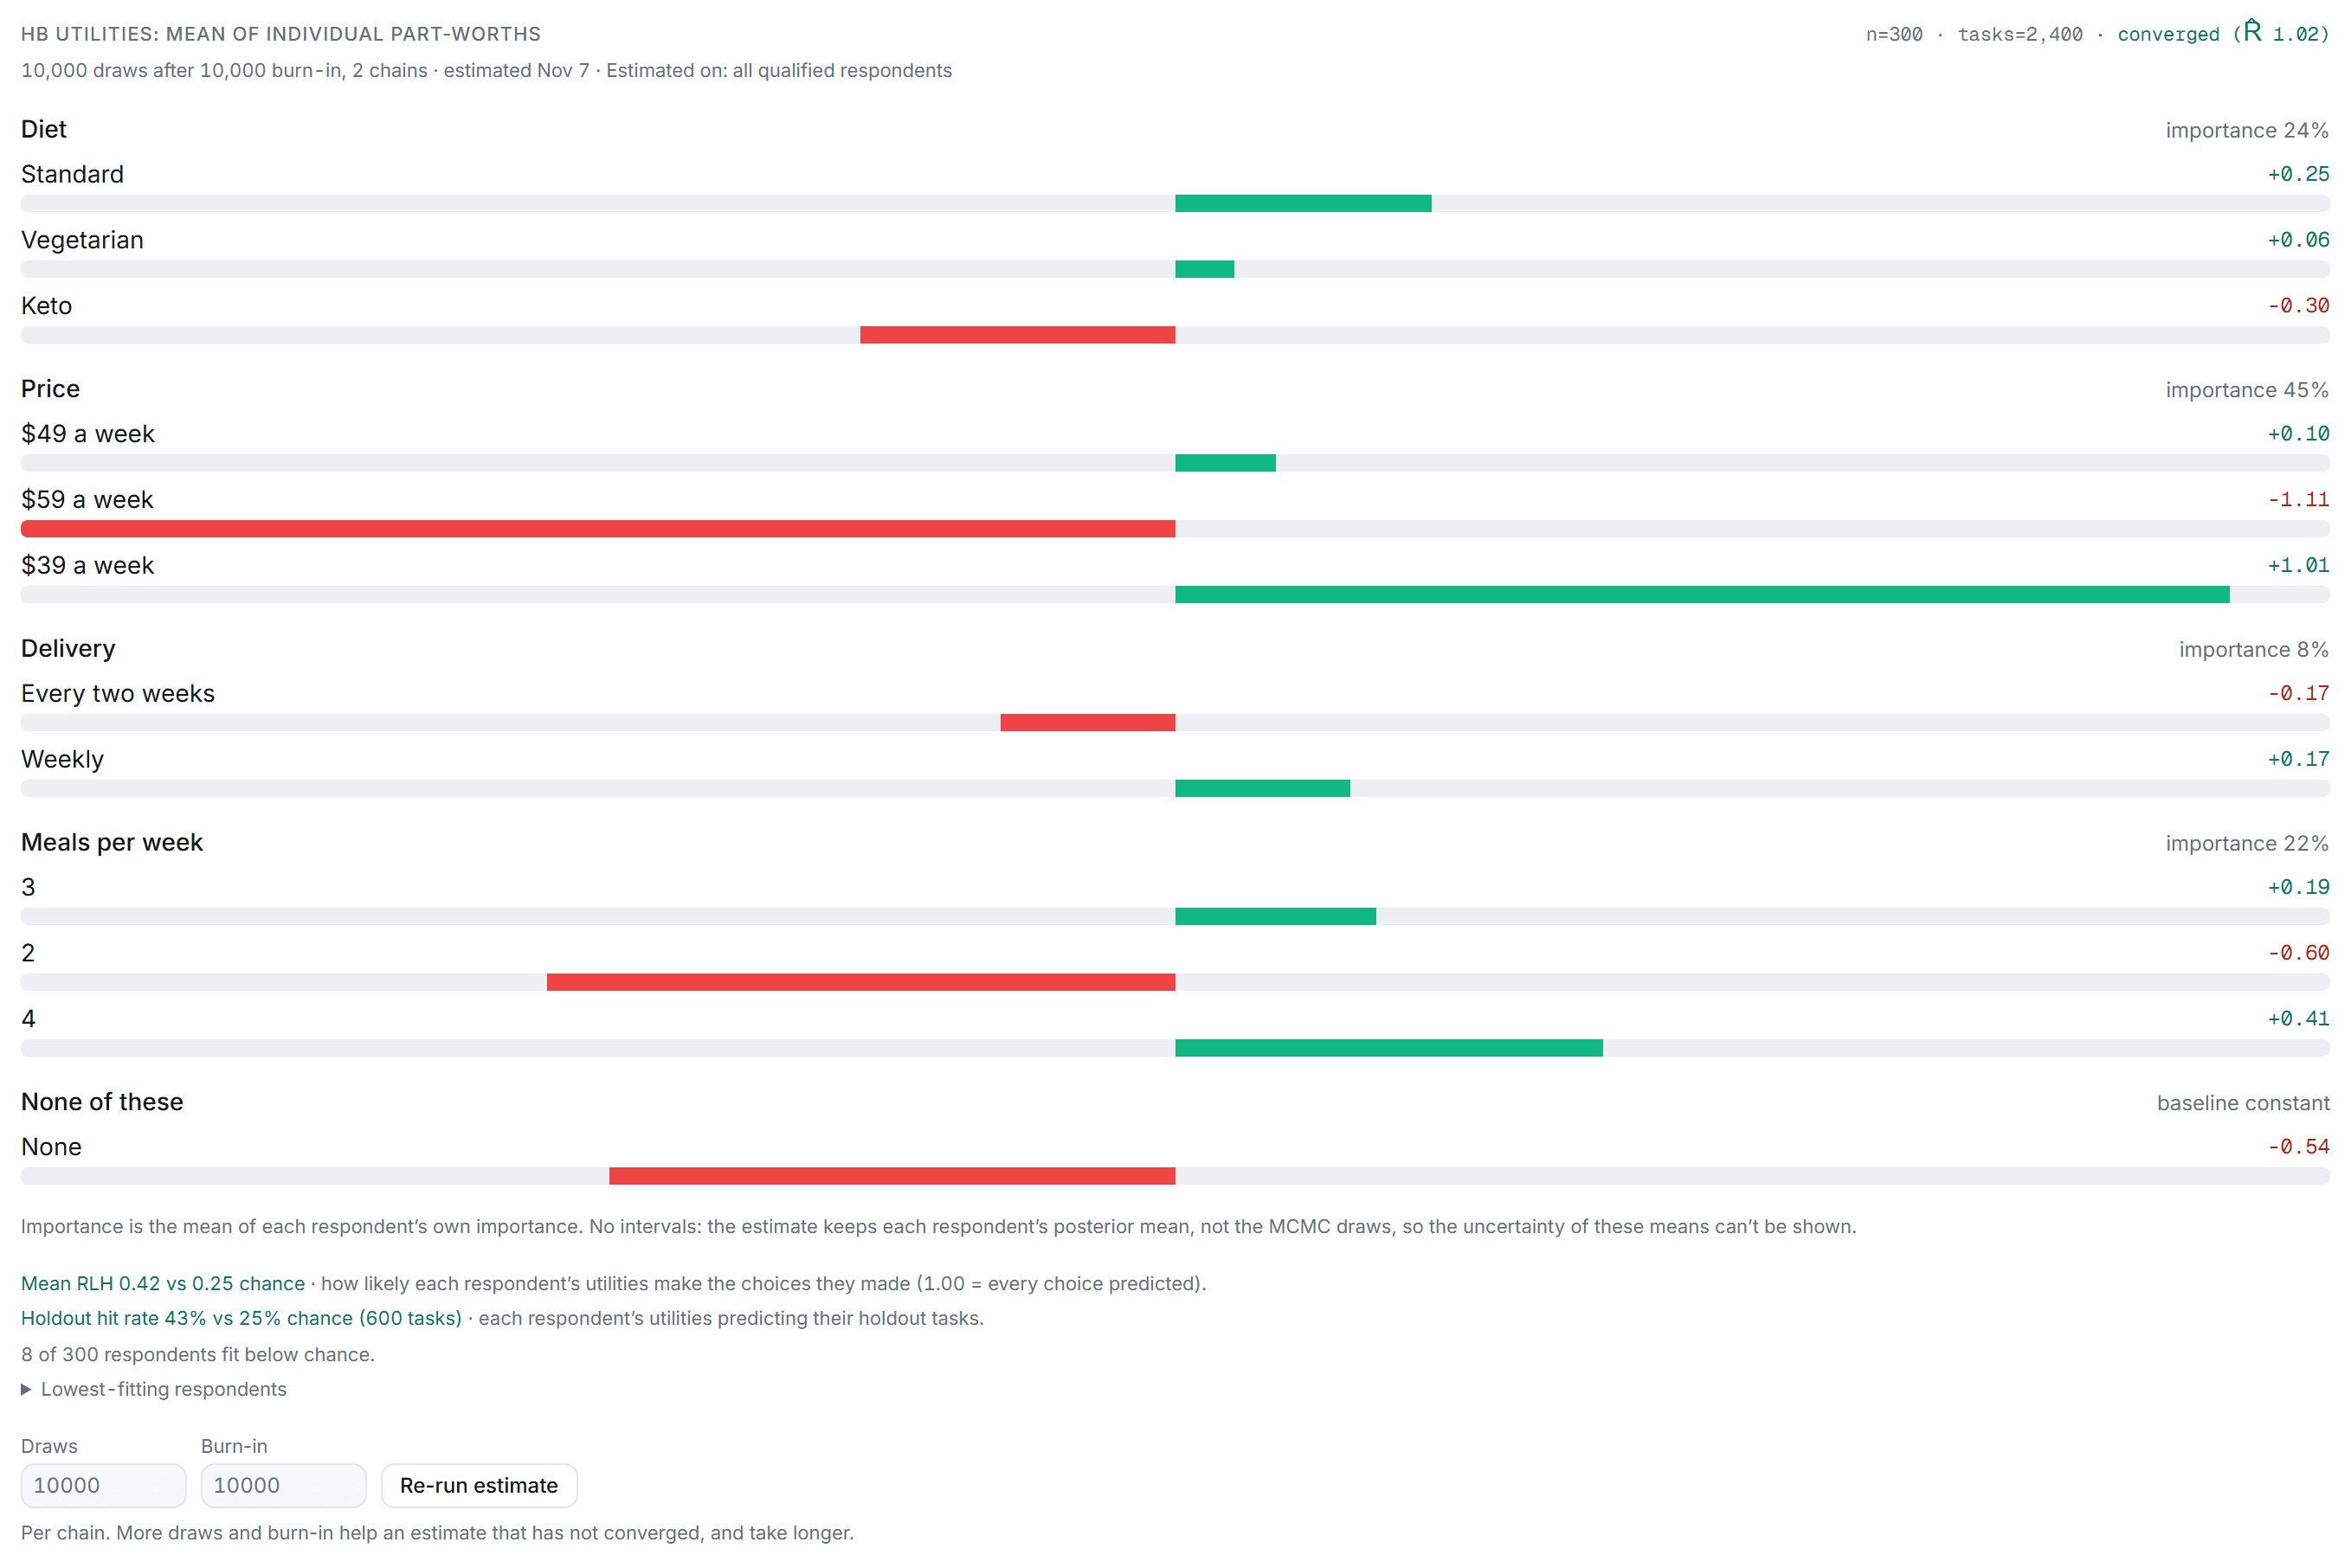
Each respondent’s part-worthsIndividual (HB) · mean and spread across the 300 respondents · R̂ 1.02, converged
Research Team| Attribute | Level | Mean | Spread (SD) | Above 0 |
|---|---|---|---|---|
| Price | $39 a week | 1.01 | 0.16 | 100% |
| $49 a week | 0.10 | 0.12 | 78% | |
| $59 a week | -1.11 | 0.12 | 0% | |
| Meals per week | 2 | -0.60 | 0.31 | 3% |
| 3 | 0.19 | 0.12 | 94% | |
| 4 | 0.41 | 0.35 | 87% | |
| Diet | Standard | 0.25 | 0.41 | 69% |
| Vegetarian | 0.06 | 0.61 | 48% | |
| Keto | -0.30 | 0.49 | 25% | |
| Delivery | Weekly | 0.17 | 0.17 | 82% |
| Every two weeks | -0.17 | 0.17 | 18% |
Price is consistent: $59 a week has a spread of 0.12 across people. Diet splits them: Vegetarian has a spread of 0.61 and is above zero for 48% of respondents. That’s the variety the simulator uses. The means are the HB panel’s; the spread and the share above zero are worked out here from the HB per respondent sheet.
By household sizeAll respondents, then Results filtered to each group · logit part-worths and importance, and HB shares
Research Team| Totaln 300 | 1 or 2 peoplen 149 | 3 or moren 151 | |
|---|---|---|---|
| Price importance | 54% | 53% | 46% |
| Meals per week importance | 25% | 18% | 27% |
| Diet importance | 12% | 21% | 19% |
| Delivery importance | 9% | 7% | 8% |
| Diet: Standard | 0.17 | -0.10 | 0.42 |
| Diet: Vegetarian | 0.06 | 0.40 | -0.28 |
| Diet: Keto | -0.22 | -0.30 | -0.14 |
| Plan A · HB share | 34% | 21% | 47% |
| Plan B · HB share | 46% | 59% | 33% |
| None · HB share | 20% | 20% | 20% |
Smaller households lean Vegetarian (0.40) over Standard (-0.10); larger ones reverse it (0.42 against -0.28), and care more about meals per week (27% importance against 18%). So Plan B wins 59% to 21% with 1 or 2 people, and Plan A wins 47% to 33% with 3 or more. Differences between groups aren’t tested.
Holdout check2 holdout tasks × 300 respondents = 600 choices the models never saw
Research TeamPredicting each holdout choice from each person’s own part-worths gets 43% right (255 of 600), against 41% for the one aggregate model and 25% by chance.
The simulatorShare-of-preference simulator · Plan A vs Plan B · all 300 respondents · “none of these” on
Research Team| Rule | Plan A$59 · 4 meals · Standard · Weekly | Plan B$49 · 3 meals · Vegetarian · Every two weeks | None of these |
|---|---|---|---|
| Individual (HB) · Share of preference | 34% | 46% | 20% |
| Individual (HB) · First choice | 43% | 56% | 0% |
| Aggregate | 31% | 47% | 22% |
A what-if of relative preference, not a market forecast. First choice gives each person’s vote to the plan they score highest, so “none” gets a vote only when it scores above both plans for that person; a tie splits the vote.

How Surveti compares
| Capability | Surveti | SurveyMonkey | Qualtrics | Alchemer | QuestionPro |
|---|---|---|---|---|---|
| Conjoint on the free or entry plan | paidResearch Team plan | no1, 5No conjoint | paid8, 9, 20A separate purchase | paid24Full Access licence only | paid29, 43Research Edition |
| Published price for conjoint | yes$449/mo, or $349/mo yearly | no1No conjoint | no9Ask your account executive | yes25Full Access $275/mo | no43Research Suite: contact sales |
| Balanced design, documented | yesLevel-balanced per respondent, though a prohibition loosens it | no1No conjoint | yes13Balanced-overlap style, in versions | partial23Cards shuffled at random | yes31Random or D-optimal |
| Design import | yesVersioned CSV, checked on submit | no1No conjoint | unclearNot covered | unclearNot described | yes31, 42Import, such as from SPSS |
| Fixed or holdout tasks | yesUp to 3, left out of the estimate, scored | no1No conjoint | unclearNot found | unclear23Not described | partial41Fixed tasks; role in estimation not stated |
| Model estimation documented | yesAggregate logit and HB | no1No conjoint | yes13, 14HB, written in STAN | partial23, 27Via an R package (HB) | partial32, 33One aggregate logit |
| Individual-level utilities | yesHB, per respondent, by respondent ID | no1No conjoint | yes13, 17Respondent-level HB | unclear23, 27Not described | unclear33Not mentioned |
| Willingness to pay | noPrice is a categorical attribute | no1No conjoint | yes15, 16Needs a pricing feature | unclear23Not described | partial39Brand premium from counts |
| Segments on conjoint results | yesResults filters, one group at a time; HB on that base when you run it | no1No conjoint | yes18Up to 12 segments in one project | partial23Sample-size advice only | partial42Filters (marketing page) |
| Built-in market simulator | yesUp to 8 products; HB share or first choice | no1No conjoint | yes16Preference share, first choice | partial23An Excel template | yes38First-choice vote count |
| Per-respondent utilities export | yesExcel workbook, keyed by respondent ID | no1No conjoint | yes17Keyed by ResponseID | unclear23Not mentioned | unclear33Not covered |
| Fit statistic (RLH) per respondent | yesRLH per respondent in the workbook; mean RLH and holdout hit rate on Results | no1No conjoint | unclear13Not documented | unclear23Not documented | unclear32Log-likelihood only |
Partial means partly built in or possible only with a documented workaround; paid means built in on paid tiers, licences or add-ons only; unclear means the vendor’s docs don’t settle it. Sawtooth Software, Conjointly and Typeform were also reviewed. Sawtooth, the conjoint specialist, has a free Discover tier up to 50 respondents per survey and documents HB, a simulator and holdout tasks left out of estimation. Conjointly offers HB conjoint from $2,895 per team per year, with a free tier limited to 20 responses. Typeform has no conjoint question.
Conjoint is on the Research Team plan: $449 a month, or $349 a month billed yearly, for 10 seats. Of the four tools we compared, only Alchemer publishes a price for conjoint, and SurveyMonkey doesn’t offer it.
Choose Run HB analysis and HB estimates each person’s part-worths, keyed by respondent ID, ready to download and join to the rest of their answers. Of the four, only Qualtrics documents a per-respondent export.
Holdout tasks are left out of the estimate and scored: a hit rate against chance. HB also gives each respondent a fit (RLH). None of the four documents a holdout hit rate or a respondent fit.
The logit fit has no random step, and Run HB analysis starts from a fixed seed, so the same data and settings give the same part-worths. Alchemer’s results can change on refresh, even without new data.
Respondents can go back to an earlier task and change their choice. Qualtrics and QuestionPro don’t support back buttons in conjoint.
Upload a versioned design, or use the built-in one. Either way every answer the survey sends is checked against the cards that person was served before it’s saved.
When to use it
“Which meal-kit plan would you choose?” Price · Meals per week · Diet · Delivery · 3 cards per task · 8 tasks + 2 holdouts · “none of these” on
Accessibility
Each task is one group of radio buttons under its question, “Which would you choose?” Tab into it, and the arrow keys move between the options and pick one, on a computer or a phone.
Every attribute and level is plain text: in a table on wider screens, where each option’s radio reads out its levels, and inside each card on phones, where the whole card is the radio. Attribute names and levels go into the translation sheet with the rest of the survey.
“Task 3 of 10” is announced when Back or Next changes the task, and focus moves to the new task’s question. A bar shows progress, and Back returns to the task before with your choice kept.
Every option, “I would not choose any of these”, Back and Next are at least 44px tall by default, with a clear focus ring in your survey’s theme, light or dark.
Use it in
Solution
Price and package a product, then see the part-worths for one group at a time with the Results filter.
Solution
Find the trade-offs before you build: which feature is worth a higher price.
Example
Plan tiers at three prices, with “none of these” to see who walks away.
Two ways. An aggregate logit model fits every choice at once and gives each attribute’s importance, and each level a part-worth with its standard error; this page draws the 95% interval as the part-worth ± 1.96 standard errors. Choose Run HB analysis on Results and Hierarchical Bayes estimates part-worths for each respondent, running in the background with a convergence check; the simulator runs on either model. The Results card also shows simple counts: how often each level was chosen when shown.
Three to six attributes with two to five levels each is typical. A task shows 2 to 6 cards (3 by default), and you can set 1 to 30 tasks (8 by default) plus up to 3 holdouts. The example uses four attributes, 3 cards and 8 tasks, so each person sees 24 cards before the holdouts.
They test the model. Everyone gets the same holdout tasks, mixed in among the others (never first, and never back to back as long as there are at least as many tasks as holdouts), and they’re left out of the estimate. Results then shows how often the model predicts the holdout choice: 43% from each person’s part-worths in the example, against 25% by chance.
Yes. Filter the Results tab by another question, such as household size, and the logit part-worths, importances and the aggregate simulator are refit for that group. HB runs on that group when you choose Run HB on this base, or Run HB analysis if there’s no estimate yet. One group shows at a time, and differences between groups aren’t tested.
The main export (CSV, Excel, and SPSS on Professional+) has one column, such as Q1, with each person’s choices: base tasks first, then the holdouts, each a card position from 0 or none. The Conjoint design (long) file in the export dialog has one row per attribute of every card shown, with the choice and the holdouts marked. Download utilities on Results gives an Excel workbook with the aggregate part-worths, their standard errors and importance, and each respondent’s HB part-worths and RLH. Answers are checked against the cards each person was served before they’re saved.
Research Team, at $449 a month or $349 a month billed yearly, alongside MaxDiff and the other advanced research types. It includes the part-worths, HB, the simulator and SPSS export.